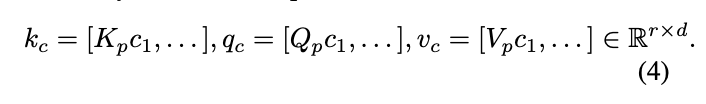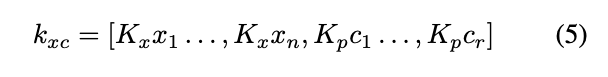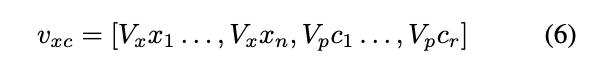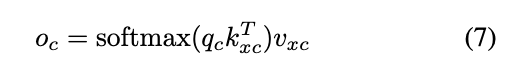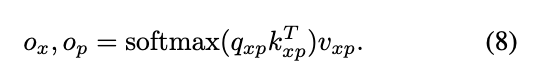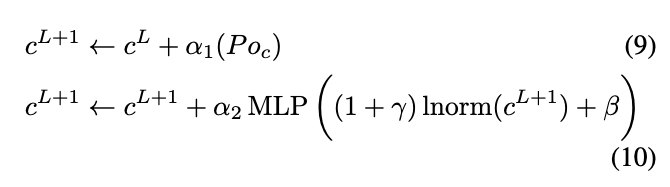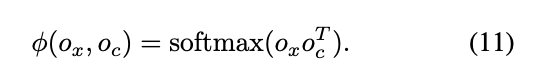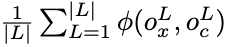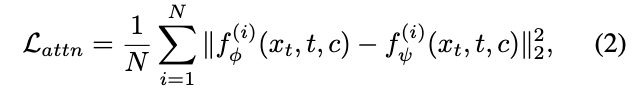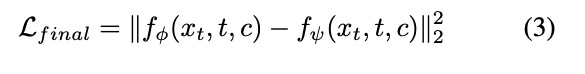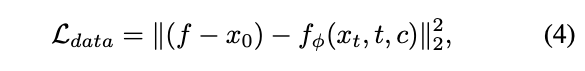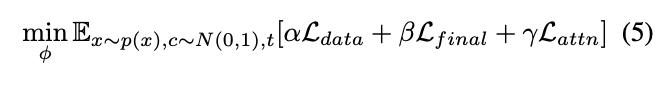<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://dianyo.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://dianyo.github.io/" rel="alternate" type="text/html" /><updated>2026-09-16T20:02:09+00:00</updated><id>https://dianyo.github.io/feed.xml</id><title type="html">Dianyo</title><subtitle>Efficient AI / Applied AI in Energy, Biology and Poultry</subtitle><entry><title type="html">Understanding kallisto: an interactive guide from reads to abundance</title><link href="https://dianyo.github.io/understanding-kallisto/" rel="alternate" type="text/html" title="Understanding kallisto: an interactive guide from reads to abundance" /><published>2026-09-16T00:00:00+00:00</published><updated>2026-09-16T00:00:00+00:00</updated><id>https://dianyo.github.io/Understanding-Kallisto</id><content type="html" xml:base="https://dianyo.github.io/understanding-kallisto/"><![CDATA[<p>RNA sequencing produces millions of short sequences called <strong>reads</strong>. The challenge is to work backward from those reads and answer two questions: Which RNA transcripts produced them, and how abundant was each transcript? Many transcripts share sequence, so a read often has several possible origins.</p>

<link rel="stylesheet" href="/assets/kallisto/vendor/katex-0.18.7/katex.min.css" />

<link rel="stylesheet" href="/assets/kallisto/article.css" />

<p><strong>kallisto estimates the abundance of each reference transcript from the collective evidence in RNA-seq reads. Using its transcriptome index, it first pseudoaligns each fragment: it determines which transcripts are compatible with the fragment without computing exact alignment coordinates. kallisto then groups fragments with the same compatibility set into equivalence classes and uses the expectation-maximization (EM) algorithm to estimate transcript abundances jointly across the sample.</strong></p>

<p>The examples below let you follow that process. You can change a sequence to see its candidates change, adjust the number of reads to change the evidence, and step through the abundance calculation. After that, we will ask whether a neural network could learn the EM calculation, explore what GPUs can accelerate, and consider why faster hardware may justify revisiting more detailed alignment methods such as Bowtie 2 + RSEM.</p>

<div class="k-roadmap" aria-label="Article contents">
  <strong>Roadmap for this article</strong>
  <ol>
    <li><a href="#the-problem">The problem: one fragment, several possible origins</a></li>
    <li>
      <a href="#k-mers">K-mers: make sequence searchable</a>
      <ul>
        <li><a href="#sequence-lab">Experiment 1: Follow a read, one k-mer at a time</a></li>
      </ul>
    </li>
    <li>
      <a href="#compatibility-classes">Compatibility classes: group reads with the same candidates</a>
      <ul>
        <li><a href="#class-lab">Experiment 2: Build your own little RNA-seq sample</a></li>
      </ul>
    </li>
    <li><a href="#effective-length">Why effective length appears</a></li>
    <li>
      <a href="#em">EM: distribute evidence, then update the estimate</a>
      <ul>
        <li><a href="#em-lab">Experiment 3: Be the EM algorithm</a></li>
      </ul>
    </li>
    <li><a href="#neural-network">Could a neural network replace EM?</a></li>
    <li><a href="#gpu">What changes on a GPU?</a></li>
    <li><a href="#bowtie2-rsem">Research direction: revisit Bowtie 2 + RSEM on GPUs</a></li>
    <li><a href="#conclusion">Conclusion: two research directions</a></li>
    <li><a href="#references">References</a></li>
  </ol>
</div>

<noscript><p class="k-note">JavaScript is disabled. The article remains readable; equations appear as LaTeX source, and the experiments require JavaScript.</p></noscript>

<h2 id="the-problem">1. The problem: one fragment, several possible origins</h2>

<p>A gene can produce several RNA transcripts through <strong>alternative splicing</strong>. These versions, called <strong>isoforms</strong>, share some sequence and differ elsewhere. RNA sequencing, usually shortened to <strong>RNA-seq</strong>, samples fragments from the RNA population. A read records the sequence at an end of a fragment and may cover only a region shared by several isoforms.</p>

<p>In paired-end sequencing, both ends of a fragment are read. The two reads provide evidence about the same fragment’s origin, so the pair is counted as one observation. The sequence examples below use one read per observation to keep the matching steps easy to follow.</p>

<p>Consider three reference transcripts, labeled T1, T2, and T3. Their sequences are only nine bases long so that every match can be inspected:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>T1   ACTGACGTA
T2   ACTGACCTA
T3   GGTGACGTA
</code></pre></div></div>

<p>The read <code class="language-plaintext highlighter-rouge">TGACGTA</code> occurs in both T1 and T3. An <strong>alignment</strong> describes where a read matches a reference, base by base, including mismatches or gaps. Even a perfect alignment of this read would leave two possible origins. Discarding it would waste evidence; counting it once for T1 and once for T3 would count the same observation twice.</p>

<p>Instead of aligning the read to the reference transcripts directly, kallisto first asks a smaller question: <strong>which transcripts are compatible with this read?</strong> Finding that candidate set is called <strong>pseudoalignment</strong>. A statistical model then uses the evidence across all reads to estimate each transcript’s contribution. This separation is central to <a href="https://www.nature.com/articles/nbt.3519">Bray, Pimentel, Melsted, and Pachter’s original paper</a>.</p>

<div class="k-flow" aria-label="Algorithm stages"><span>Read sequences</span><span>→ candidate sets</span><span>→ class counts</span><span>→ abundance</span></div>

<p>The reference transcriptome is the collection of transcript sequences supplied to kallisto. Its abundance estimates describe transcripts in that collection; a transcript missing from the reference cannot receive its own estimate.</p>

<h2 id="k-mers">2. K-mers: make sequence searchable</h2>

<p>A <strong>k-mer</strong> is a stretch of k consecutive bases. Set k to 3, slide a three-base window along <code class="language-plaintext highlighter-rouge">TGACGTA</code>, and the read becomes five overlapping windows:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>TGA
 GAC
  ACG
   CGT
    GTA
</code></pre></div></div>

<p>A read of length <span class="k-math">\(L\)</span> has <span class="k-math">\(L-k+1\)</span> such windows when <span class="k-math">\(L\geq k\)</span>. An <strong>index</strong> makes the windows searchable: for each distinct k-mer, it records which reference transcripts contain it. Here, <code class="language-plaintext highlighter-rouge">TGA</code> occurs in all three transcripts, while <code class="language-plaintext highlighter-rouge">ACG</code> occurs in T1 and T3. A transcript either belongs to that candidate set or does not; repeated occurrences within it do not add extra transcript identities.</p>

<aside class="k-try" aria-label="Try it">
  <p><strong>Try it:</strong> leave k at 3 and select <strong>Shared read</strong>. Click <code class="language-plaintext highlighter-rouge">TGA</code>, then <code class="language-plaintext highlighter-rouge">ACG</code>. TGA leaves all three transcripts possible; ACG removes T2. Next, select <strong>Unique read</strong> and follow its windows. Its beginning is shared with T2 and its end is shared with T3, but only T1 survives both pieces of evidence.</p>
</aside>

<section class="k-lab" id="sequence-lab" aria-labelledby="sequence-lab-title">
  <p class="k-eyebrow">Experiment 1 · Sequence → compatibility</p>
  <h3 id="sequence-lab-title">Follow a read, one k-mer at a time</h3>
  <p class="k-help">Change k or edit the read. Click a k-mer to see its matches and the intersection so far.</p>
  <div class="k-controls">
    <label class="k-grow" for="k-read">Read sequence
      <input id="k-read" type="text" value="TGACGTA" maxlength="60" spellcheck="false" autocapitalize="characters" autocomplete="off" aria-describedby="k-read-help" />
    </label>
    <label for="k-size">k = <output id="k-size-value">3</output>
      <input id="k-size" type="range" min="2" max="7" step="1" value="3" />
    </label>
  </div>
  <p id="k-read-help" class="k-help">Enter 2–60 A/C/G/T bases; spaces are ignored. Sequences are compared in the orientation shown.</p>
  <div class="k-buttons k-example-reads" aria-label="Example reads">
    <button type="button" data-read="TGACGTA" aria-pressed="true"><strong>Shared read</strong><span>Occurs in T1 and T3</span></button>
    <button type="button" data-read="ACTGACG" aria-pressed="false"><strong>Unique read</strong><span>Occurs only in T1</span></button>
    <button type="button" data-read="ACTGTCGT" aria-pressed="false"><strong>One substitution</strong><span>One base differs from a T1 segment</span></button>
    <button type="button" data-read="AAAAAAA" aria-pressed="false"><strong>No matches</strong><span>No k-mer occurs in the index</span></button>
  </div>
  <p id="k-example-description" class="k-example-description k-help" aria-live="polite"></p>
  <div id="k-read-window" class="k-sequence" aria-label="Read with the current k-mer highlighted"></div>
  <div id="k-kmers" class="k-kmers" aria-label="Read k-mers"></div>
  <div class="k-buttons">
    <button type="button" id="k-prev">← Previous</button>
    <button type="button" id="k-next">Next k-mer →</button>
    <span id="k-step-label" class="k-help"></span>
  </div>
  <div id="k-transcripts" class="k-transcripts"></div>
  <div id="k-intersection" class="k-result" role="status" aria-live="polite"></div>
  <div id="k-read-result" class="k-help"></div>
  <details>
    <summary>Inspect the complete k-mer index</summary>
    <p class="k-help" id="k-index-summary"></p>
    <div class="k-table-scroll" tabindex="0" role="region" aria-label="K-mer index table">
      <table><thead><tr><th scope="col">k-mer</th><th scope="col">Transcript set C(k-mer)</th></tr></thead><tbody id="k-index"></tbody></table>
    </div>
  </details>
</section>

<p>The operation above is a <strong>set intersection</strong>: retain only the transcripts that appear in every matching k-mer window’s candidate set. Let <span class="k-math">\(C(\cdot)\)</span> denote a candidate set:</p>

<div class="k-equation">
\[
\begin{aligned}
C(\mathtt{TGACGTA})
  &amp;= C(\mathtt{TGA}) \cap C(\mathtt{GAC}) \\
  &amp;\quad \cap C(\mathtt{ACG}) \cap C(\mathtt{CGT}) \cap C(\mathtt{GTA}) \\
  &amp;= \{T_1,T_2,T_3\} \cap \{T_1,T_3\} \\
  &amp;= \{T_1,T_3\}.
\end{aligned}
\]
</div>

<p>The final answer <span class="k-math">\(\{T_1,T_3\}\)</span> means either transcript could be the origin. It does not yet assign a probability to either one. Also notice that the five windows still represent <strong>one read</strong>. They help determine its candidates; <strong>they do not become five separate observations in the abundance calculation</strong>.</p>

<h3 id="what-changing-k-teaches-us">What changing k teaches us</h3>

<p>Small k-mers occur more readily by chance. Longer k-mers can distinguish sequences better, but give a short read fewer windows. A single changed base also affects every window that overlaps it.</p>

<aside class="k-try" aria-label="Try it">
  <p><strong>Try it:</strong> in the <a href="#sequence-lab">interactive experiment above</a>, select <strong>One substitution</strong> at k = 3. A substitution replaces one base with another. Some windows now fail to match, while unaffected windows can still identify a candidate. Increase k and watch how many matching windows remain. Then select <strong>No matches</strong> to see what happens when none of the windows supplies evidence.</p>
</aside>

<p>An <strong>absent k-mer is skipped rather than treated as an empty candidate set</strong> in this intersection procedure. If none of the windows matches, the read is <strong>unassigned</strong>. A read is also unassigned when its matching windows point to incompatible sets with no transcript in common. A changed base can sometimes create a match elsewhere in the reference, so surviving matches are evidence rather than a guarantee of the true origin.</p>

<p>For these short examples, k ranges from 2 to 7 and sequences are compared in their written orientation. Real RNA-seq requires attention to read orientation and paired ends. kallisto’s documented index default is k = 31, with an odd-k requirement; those settings are described in the <a href="https://pachterlab.github.io/kallisto/manual">kallisto manual</a>.</p>

<h3 id="where-the-graph-fits">Where the graph fits</h3>

<p>Notice that several consecutive windows can have identical candidate sets. Once <span class="k-math">\(\{T_1,T_3\}\)</span> is the running answer, intersecting it with <span class="k-math">\(\{T_1,T_3\}\)</span> again changes nothing. <strong>Avoiding redundant work is one source of kallisto’s speed.</strong></p>

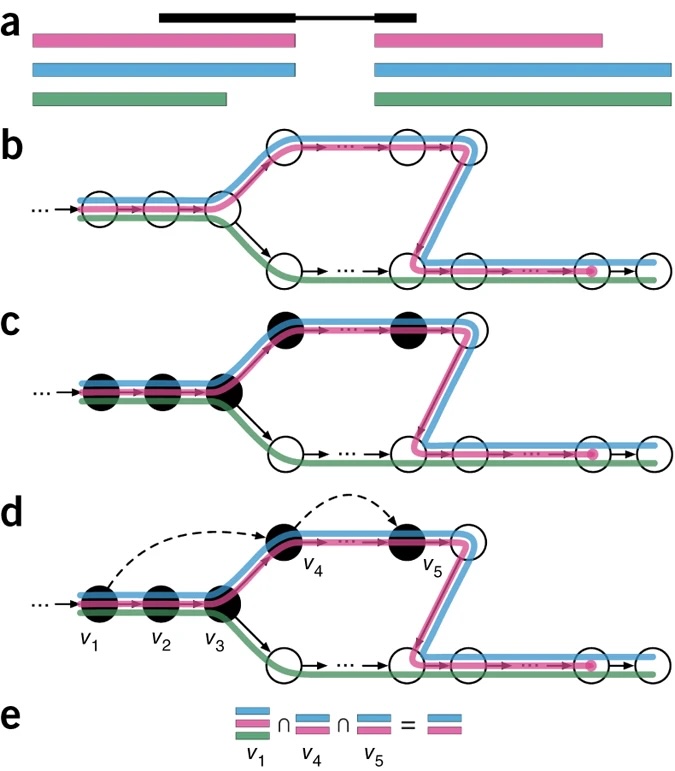
<p>The original index organizes k-mers into a <strong>transcriptome de Bruijn graph (T-DBG)</strong>. K-mers are nodes, neighboring sequence windows connect them, and transcript membership supplies their “colors.” Each transcript follows a path through the graph. Linear stretches with unchanged membership can be compacted into <strong>contigs</strong>, which may cover only part of a transcript. kallisto uses this structure to skip redundant lookups and checks the end of a skip.</p>

<figure class="k-paper-figure k-paper-graph" id="kallisto-graph-overview">
  <a href="/images/kallisto/figure-0-kallisto.jpg" aria-label="Open the original kallisto graph overview at full size">
    <img src="/images/kallisto/figure-0-kallisto.jpg" width="675" height="771" loading="lazy" alt="Five-panel overview of kallisto. Three colored transcripts form paths through a transcriptome de Bruijn graph of k-mer nodes. Read k-mers are marked on the graph, dotted arrows skip redundant nodes, and the remaining transcript sets are intersected." />
  </a>
  <figcaption>Figure 1, “Overview of kallisto,” from <a href="https://doi.org/10.1038/nbt.3519">Bray, Pimentel, Melsted, and Pachter (2016)</a>. © 2016 Springer Nature. Select the image to enlarge it.</figcaption>
</figure>

<p>The figure makes the role of contigs concrete. In panel <strong>b</strong>, each circle is a k-mer and each colored line is a transcript path. Consecutive circles along a nonbranching stretch can be stored as one contig when they carry the same set of transcript colors. In panel <strong>d</strong>, the dotted arrows show kallisto jumping over k-mers whose candidate set would repeat the same information; the labeled nodes mark lookup points and skip endpoints. Panel <strong>e</strong> intersects the transcript sets from those informative points to obtain the read’s compatibility set.</p>

<p>The final candidate set has limits: it does not retain the order and positions of every match. With very small k, a string can pass the intersection test even when it does not occur as one continuous sequence in a transcript. This is one reason the choice of k matters.</p>

<h2 id="compatibility-classes">3. Compatibility classes: group reads with the same candidates</h2>

<p>After pseudoalignment, many reads have the same candidate set. Grouping them reduces the data passed to abundance estimation. Three terms describe the successive stages:</p>

<ul>
  <li>A <strong>k-mer compatibility set</strong> contains transcripts that contain that k-mer.</li>
  <li>A <strong>read or fragment compatibility set</strong> contains candidates surviving the combined evidence.</li>
  <li>An <strong>equivalence class (EC)</strong> groups observations with the same final candidate set. Its count is the number of observations in that group. These are also called transcript compatibility counts (TCCs).</li>
</ul>

<p>For example, <span class="k-math">\(\{T_1,T_2\}:90\)</span> means ninety reads could have come from T1 or T2. Their origins are still unresolved. The grouping records one count of ninety, which the abundance model will divide between candidates.</p>

<aside class="k-try" aria-label="Try it">
  <p><strong>Try it:</strong> change the copies of <code class="language-plaintext highlighter-rouge">ACTGACG</code> from 100 to 200. At k = 3, this adds evidence to the <span class="k-math">\(\{T_1\}\)</span> class. Move the k slider in this experiment and watch the same reads regroup; at k = 7, reads shorter than seven bases become unassigned. Set a row’s copies to 0 to remove its evidence, or use <strong>Restore sample</strong> to return to the default counts and k = 3. Press <strong>Use these class counts in EM</strong> to send the assigned counts to the <a href="#em-lab">abundance experiment in section 5</a>.</p>
</aside>

<section class="k-lab" id="class-lab" aria-labelledby="class-lab-title">
  <p class="k-eyebrow">Experiment 2 · Compatibility → counts</p>
  <h3 id="class-lab-title">Build your own little RNA-seq sample</h3>
  <p class="k-help">Each row represents one read sequence observed multiple times. Choose k here and edit the number of copies directly; set the number to 0 to remove that sequence's evidence.</p>
  <div class="k-controls">
    <label for="k-class-size">k = <output id="k-class-size-value">3</output>
      <input id="k-class-size" type="range" min="2" max="7" step="1" value="3" />
    </label>
    <button type="button" id="k-reset-reads">Restore sample</button>
  </div>
  <p id="k-sample-message" class="k-help" role="status"></p>
  <div class="k-table-scroll" tabindex="0" role="region" aria-label="Read compatibility matrix">
    <table>
      <caption>Compatibility matrix. A colored 1 means compatible; 0 means not compatible.</caption>
      <thead><tr><th scope="col">Read</th><th scope="col">Copies</th><th scope="col">T1</th><th scope="col">T2</th><th scope="col">T3</th></tr></thead>
      <tbody id="k-read-matrix"></tbody>
    </table>
  </div>
  <p id="k-sample-totals" class="k-result" role="status" aria-live="polite"></p>
  <div id="k-classes" class="k-class-list"></div>
  <button type="button" id="k-use-sample" class="k-primary">Use these class counts in EM ↓</button>
  <p class="k-help">Only assigned reads enter the likelihood. The button copies your current counts and resets EM with equal effective lengths. Later edits to this sample take effect in EM when you press it again.</p>
</section>

<h3 id="what-does-grouping-preserve">What does grouping preserve?</h3>

<p>Consider a compatibility matrix as a table with a row for each read and a column for each transcript. 1 means the transcript remains a candidate; 0 means it does not:</p>

<div class="k-equation">
\[
\begin{array}{c|ccc}
 &amp; T_1 &amp; T_2 &amp; T_3 \\ \hline
\text{read A} &amp; 1 &amp; 1 &amp; 0 \\
\text{read B} &amp; 1 &amp; 1 &amp; 0 \\
\text{read C} &amp; 1 &amp; 0 &amp; 0 \\
\text{read D} &amp; 1 &amp; 1 &amp; 0
\end{array}
\]
</div>

<p>The grouped version is <span class="k-math">\(\{T_1,T_2\}:3\)</span> and <span class="k-math">\(\{T_1\}:1\)</span>. It preserves how often each candidate set occurs, but not the identities or order of the reads that produced those sets. You cannot reconstruct the original labeled table from the counts alone.</p>

<p>For abundance estimation, however, those repeated rows ask the model exactly the same question. A <strong>likelihood</strong> measures how well a proposed mixture of transcripts explains the observed evidence. Each repeated row contributes the same factor to that likelihood, so multiplying it three times is equivalent to raising it to the third power.</p>

<p>In symbols, let <span class="k-math">\(\alpha_t\)</span> be the probability that a sampled fragment comes from <span class="k-math">\(t\)</span>, and <span class="k-math">\(\ell_t\)</span> its effective length, explained next. Let <span class="k-math">\(e\)</span> denote a candidate set and <span class="k-math">\(c_e\)</span> its count. Here <span class="k-math">\(F\)</span> contains the assigned fragments and <span class="k-math">\(E\)</span> contains their equivalence classes. kallisto’s basic likelihood can be written as:</p>

<div class="k-equation">
\[
\begin{aligned}
g_e(\boldsymbol{\alpha})
  &amp;= \sum_{t\in e}\frac{\alpha_t}{\ell_t},
  \quad \alpha_t\geq 0,
  \quad \sum_t\alpha_t=1, \\
\mathcal{L}(\boldsymbol{\alpha})
  &amp;\propto \prod_{f\in F}g_{C(f)}(\boldsymbol{\alpha})
  = \prod_{e\in E}\bigl[g_e(\boldsymbol{\alpha})\bigr]^{c_e}.
\end{aligned}
\]
</div>

<p>For the four fragments above, three belong to the compatibility class <span class="k-math">\(\{T_1,T_2\}\)</span>, and one belongs to <span class="k-math">\(\{T_1\}\)</span>. Therefore, their equivalence-class counts are <span class="k-math">\(c_{\{T_1,T_2\}}=3\)</span> and <span class="k-math">\(c_{\{T_1\}}=1\)</span>. Writing <span class="k-math">\(g_{12}\)</span> as shorthand for <span class="k-math">\(g_{\{T_1,T_2\}}\)</span>, the fragment-level likelihood <span class="k-math">\(g_{12}g_{12}g_1g_{12}\)</span> becomes <span class="k-math">\(g_{12}^{3}g_1\)</span>. These <strong>equivalence-class counts</strong> are sufficient statistics for this likelihood: they retain everything needed to calculate it.</p>

<h2 id="effective-length">4. Why effective length appears</h2>

<p>Imagine two transcripts present in equal numbers of RNA molecules, but one offers twice as many possible fragment starts. It can contribute more fragments simply because it is longer. <strong>Fragment share</strong> <span class="k-math">\(\alpha\)</span> therefore differs from the transcript’s share of the RNA molecules.</p>

<p><strong>Effective length</strong> accounts for the available fragment starts. For a transcript of length <span class="k-math">\(L\)</span> and a fixed fragment length <span class="k-math">\(d\leq L\)</span>, a simple effective length is <span class="k-math">\(\ell=L-d+1\)</span>. A 1,000-base transcript with 200-base fragments, for example, has 801 possible starts. Real library models account for a distribution of fragment lengths.</p>

<p>The basic model describes two choices: select transcript <span class="k-math">\(t\)</span> with probability <span class="k-math">\(\alpha_t\)</span>, then select one of its possible fragment locations. The second choice contributes the inverse-length factor. That is why a compatible transcript contributes <span class="k-math">\(\alpha/\ell\)</span> to the likelihood term.</p>

<p>With equal fragment shares but effective lengths 100 and 200, a shared observation has relative weights <span class="k-math">\(\frac{0.5}{100}:\frac{0.5}{200}=2:1\)</span>. You can explore this by changing effective lengths in the <a href="#em-lab">EM controls experiment</a>.</p>

<h2 id="em">5. EM: distribute evidence, then update the estimate</h2>

<p>Suppose the sample contains many fragments unique to T1 but only a few unique to T2. Dividing every fragment shared by T1 and T2 equally would ignore that imbalance. Evidence from the whole sample should influence the division.</p>

<p><strong>Expectation-maximization (EM)</strong> does this in two repeating steps. The <strong>E-step</strong> uses the current abundance estimate to divide ambiguous evidence. The <strong>M-step</strong> adds up those assignments and uses the totals as the next abundance estimate. The origin of each ambiguous fragment is the hidden information being estimated.</p>

<p>For a class <span class="k-math">\(e\)</span>, the fraction allocated to a compatible transcript is called its <strong>responsibility</strong>, written <span class="k-math">\(w_{e,t}\)</span>. It is that transcript’s <span class="k-math">\(\alpha/\ell\)</span> weight divided by the total weight of the candidates:</p>

<div class="k-equation">
\[
\begin{aligned}
w_{e,t} &amp;= \begin{cases}
\displaystyle\frac{\alpha_t/\ell_t}{\sum_{j\in e}\alpha_j/\ell_j}, &amp; t\in e, \\[8pt]
0, &amp; t\notin e,
\end{cases} \\
n_t &amp;= \sum_{e\in E}c_e\,w_{e,t}.
\end{aligned}
\]
</div>

<p>Responsibilities within a class sum to one. Multiplying them by the class count divides its evidence without duplicating it. Summing those fractional assignments gives expected transcript counts <span class="k-math">\(n_t\)</span>. The M-step is then:</p>

<div class="k-equation">
\[
\alpha_t^{\mathrm{new}}=\frac{n_t}{N},
\qquad N=\sum_{e\in E}c_e.
\]
</div>

<p>The M-step simply divides expected counts by <span class="k-math">\(N\)</span>; <span class="k-math">\(\alpha\)</span> remains a fragment fraction.</p>

<h3 id="a-calculation-you-can-reproduce">A calculation you can reproduce</h3>

<p>Take 100 observations unique to T1, 10 unique to T2, and 90 compatible with both. Use equal effective lengths and equal starting weights. T3 has no supporting class here.</p>

<p>The first E-step splits the ninety shared observations 45/45. Expected counts are <span class="k-math">\((145,55,0)\)</span>, so the M-step yields <span class="k-math">\((0.725,0.275,0)\)</span>. The next E-step allocates <span class="k-math">\(90\times0.725=65.25\)</span> to T1 and 24.75 to T2. Updating gives <span class="k-math">\((0.82625,0.17375,0)\)</span>.</p>

<aside class="k-try" aria-label="Try it">
  <p><strong>Try it:</strong> select <strong>Worked example</strong> and press <strong>Animate E/M from start</strong>. The E-step highlights while the class counts are divided; the M-step then highlights while the transcript shares and trajectory are updated. The animation shows the early cycles individually and accelerates through later checkpoints until convergence. To reproduce the arithmetic yourself, reset EM, press <strong>E-step: split counts</strong>, check the 45/45 split, and press <strong>M-step: update α</strong>. Repeat once to obtain <span class="k-math">\((0.82625,0.17375,0)\)</span>.</p>
</aside>

<section class="k-lab" id="em-lab" aria-labelledby="em-lab-title">
  <p class="k-eyebrow">Experiment 3 · Counts → abundance</p>
  <h3 id="em-lab-title">Be the EM algorithm</h3>
  <label for="k-em-preset">Choose a data set
    <select id="k-em-preset">
      <option value="worked">Worked example: 100 unique / 10 unique / 90 shared</option>
      <option value="slow">Slow convergence: 1 unique / 999 shared</option>
      <option value="ambiguous">Unidentifiable: only shared fragments</option>
      <option value="custom">My class counts</option>
    </select>
  </label>
  <details>
    <summary>Edit class counts, effective lengths, and initialization</summary>
    <p class="k-help">Change the evidence or the starting estimate to see how EM responds. Effective lengths are independent of the short sequences in experiment 1. Any edit restarts EM.</p>
    <div id="k-em-counts" class="k-count-grid"></div>
    <div class="k-table-scroll" tabindex="0" role="region" aria-label="EM parameters">
      <table><thead><tr><th scope="col">Transcript</th><th scope="col">Effective length ℓ</th><th scope="col">Starting weight</th></tr></thead><tbody id="k-em-parameters"></tbody></table>
    </div>
    <p class="k-help">Starting weights are normalized to sum to 1. Keep them positive so a possible transcript is not permanently excluded.</p>
  </details>
  <div class="k-buttons">
    <button type="button" id="k-em-animate" class="k-primary" aria-pressed="false">Animate E/M from start</button>
    <button type="button" id="k-em-step">E-step: split counts</button>
    <button type="button" id="k-em-run">Run to convergence</button>
    <button type="button" id="k-em-reset">Reset EM</button>
    <button type="button" id="k-em-favor">Start favoring T1</button>
  </div>
  <div id="k-em-cycle" class="k-em-cycle" aria-label="EM animation stages">
    <div id="k-em-phase-e" class="k-em-phase" data-active="false"><strong>E-step</strong><span>Split each class count</span></div>
    <span class="k-em-arrow" aria-hidden="true">→</span>
    <div id="k-em-phase-m" class="k-em-phase" data-active="false"><strong>M-step</strong><span>Update transcript shares</span></div>
  </div>
  <p class="k-help">The animation restarts from the selected initial weights. It shows the early cycles, then uses representative checkpoints when convergence takes many iterations.</p>
  <p id="k-em-status" class="k-result" role="status" aria-live="polite"></p>
  <div id="k-em-class-summary" class="k-help"></div>
  <div id="k-em-bars" class="k-abundance"></div>
  <div class="k-table-scroll" tabindex="0" role="region" aria-label="Transcript abundance estimates">
    <table><caption>Current estimate (α is fragment share)</caption><thead><tr><th scope="col">Transcript</th><th scope="col">α</th><th scope="col">N × α</th><th scope="col">TPM</th></tr></thead><tbody id="k-em-estimates"></tbody></table>
  </div>
  <figure class="k-chart"><svg id="k-em-chart" viewBox="0 0 600 190" role="img" aria-label="Transcript fragment shares across EM iterations"></svg><figcaption id="k-em-chart-caption" class="k-help"></figcaption></figure>
  <div id="k-e-step" hidden="">
    <div class="k-table-scroll" tabindex="0" role="region" aria-label="E-step fractional assignments">
      <table><caption>E-step: expected fragments from each class (c × w)</caption><thead><tr><th scope="col">Class (count)</th><th scope="col">To T1</th><th scope="col">To T2</th><th scope="col">To T3</th></tr></thead><tbody id="k-e-allocations"></tbody><tfoot id="k-e-totals"></tfoot></table>
    </div>
    <p class="k-help">Each row sums to its class count. The M-step divides each column total by N to get the next α.</p>
  </div>
  <p id="k-em-likelihood" class="k-help"></p>
  <p class="k-help">This experiment stops when the largest change in a transcript's fragment share is below <span class="k-math">\(10^{-8}\)</span>, with a limit of 2,000 updates per run. kallisto uses its own convergence criteria.</p>
</section>

<p>In this example, the final T1:T2 ratio is set by the unique evidence: <span class="k-math">\(100:10\)</span>. Running EM to convergence gives approximately <span class="k-math">\((0.90909,0.09091,0)\)</span>. The ninety shared fragments add to the estimated counts but cannot distinguish those two transcripts by themselves.</p>

<h3 id="why-estimated-counts-and-tpm-differ">Why estimated counts and TPM differ</h3>

<p>Fractional assignments naturally give noninteger estimated counts. Once EM has fit the fragment shares, the estimated count for a transcript is <span class="k-math">\(N\alpha\)</span>. To account for transcript length, divide these counts by effective length and scale the resulting shares to a total of one million. The result is <strong>TPM</strong>, or transcripts per million:</p>

<div class="k-equation">
\[
r_t=\frac{n_t}{\ell_t},
\qquad
\mathrm{TPM}_t=10^6\frac{r_t}{\sum_j r_j}.
\]
</div>

<p>TPM sums to one million when the total is positive. It equals <span class="k-math">\(\alpha\)</span> multiplied by a million only when the effective lengths are equal. Compare the <span class="k-math">\(\alpha\)</span> and TPM columns after changing the lengths: they answer different questions about the same sample. At iteration zero, <span class="k-math">\(N\alpha\)</span> is only an initial guess; after fitting, it is an estimated fragment count rather than a direct count of original RNA molecules.</p>

<h3 id="can-a-stable-answer-still-be-ambiguous">Can a stable answer still be ambiguous?</h3>

<p>Select <strong>Unidentifiable</strong>. Only <span class="k-math">\(\{T_1,T_2\}\)</span> appears, and the effective lengths are equal. No observation distinguishes the two transcripts. Once <span class="k-math">\(\alpha_3=0\)</span>, the likelihood depends on <span class="k-math">\(\alpha_1+\alpha_2\)</span>, so every split with that sum equal to one fits equally well.</p>

<aside class="k-try" aria-label="Try it">
  <p><strong>Try it:</strong> run with equal starting weights, then click <strong>Start favoring T1</strong> and run again. The T1/T2 splits differ, but the final likelihood is the same. The starting weights selected a split that the observations themselves could not determine.</p>
</aside>

<p>This is a lack of <strong>identifiability</strong>: the evidence does not determine a unique answer. More reads from exactly the same shared class cannot resolve it; distinguishing reads or additional assumptions are needed. A stable optimizer is therefore only one part of interpreting an abundance estimate.</p>

<p>The sections so far cover kallisto’s core path from reads to abundance. The remaining sections use that foundation to ask how learned surrogates and modern GPUs might change the algorithm.</p>

<h2 id="neural-network">6. Could a neural network replace EM?</h2>

<p>Neural networks are increasingly used in scientific computing to approximate calculations that would otherwise require an expensive numerical solver. Such a network is often called a <strong>surrogate model</strong>: it is trained on input–output examples from the original calculation and then learns a faster approximation to that mapping. A prominent example is the <a href="https://arxiv.org/abs/2010.08895">Fourier Neural Operator</a>, which learns mappings from the inputs of partial differential equations to their solutions across a family of problems, rather than solving each instance independently from the beginning.</p>

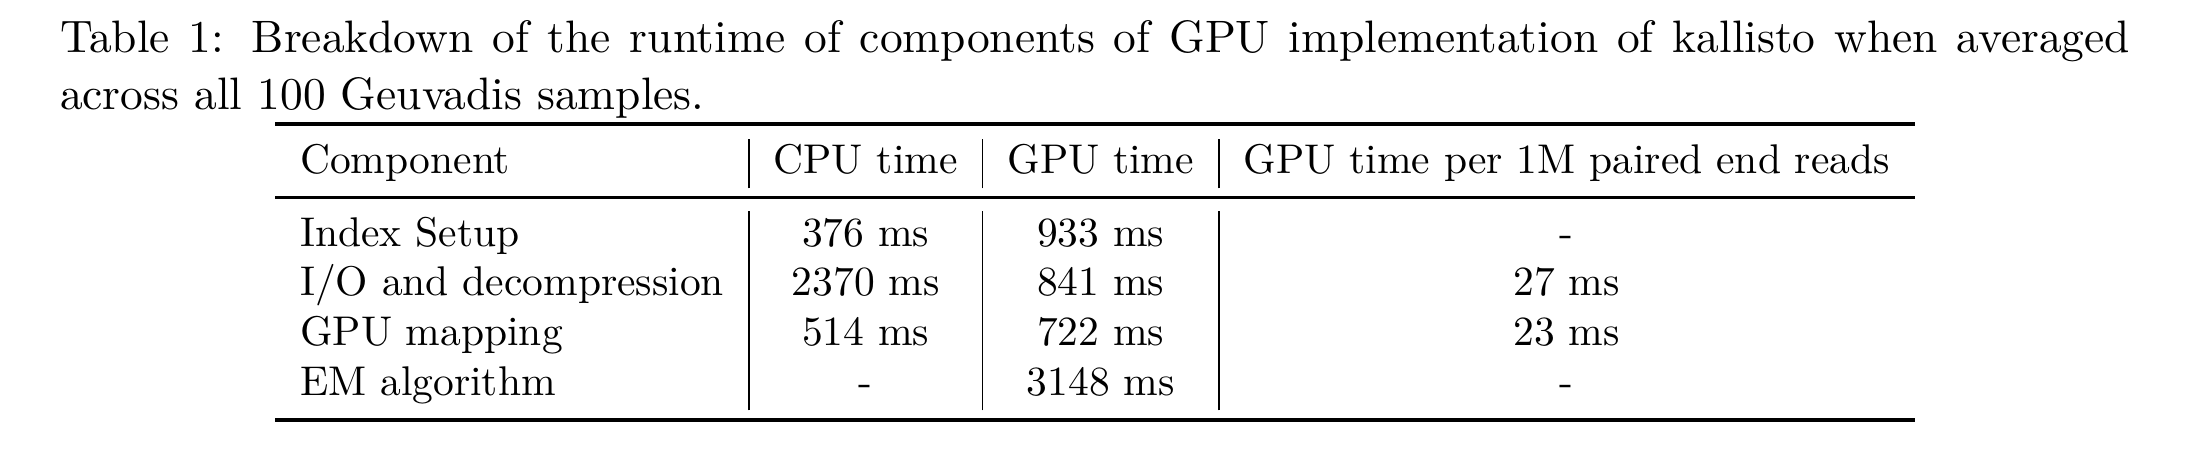
<p>Transcript quantification suggests a related opportunity. After pseudoalignment has reduced the reads to equivalence-class counts, EM repeatedly redistributes those counts and updates transcript abundances until convergence. The 2026 <a href="https://www.biorxiv.org/content/10.64898/2026.03.04.709526v1.full.pdf">GPU kallisto study</a> makes the remaining cost visible: in its average timing breakdown, GPU mapping takes 722 ms while EM takes 3,148 ms. Accelerating k-mer lookup therefore exposes abundance estimation as a major part of the computation.</p>

<p>There is already research connecting neural networks and EM. <a href="https://papers.neurips.cc/paper/7246-neural-expectation-maximization">Neural Expectation Maximization</a> constructs a differentiable EM-like procedure in which a neural network learns the statistical model used for perceptual grouping. <a href="https://openaccess.thecvf.com/content/CVPR2025/html/Zhou_UNEM_UNrolled_Generalized_EM_for_Transductive_Few-Shot_Learning_CVPR_2025_paper.html">UNEM</a> takes another route: it unfolds the iterations of a generalized EM algorithm into network layers and learns iteration-specific parameters for few-shot classification. Neither paper studies RNA-seq, but both show that the repeated structure of EM can be exposed to learning.</p>

<p>This raises a research question for transcript quantification: <strong>can a neural network learn the EM computation that maps equivalence-class evidence to transcript abundances?</strong></p>

<h2 id="gpu">7. What changes on a GPU?</h2>

<p>Modern GPUs can run thousands of small operations at the same time, and their memory bandwidth has increased along with their computing power. kallisto contains work that can be separated naturally: different fragments can look up k-mers independently, different candidate sets can be intersected independently, and different equivalence classes can contribute to an EM update in parallel.</p>

<h3 id="a-coauthor-revisits-kallisto-on-a-gpu">A coauthor revisits kallisto on a GPU</h3>

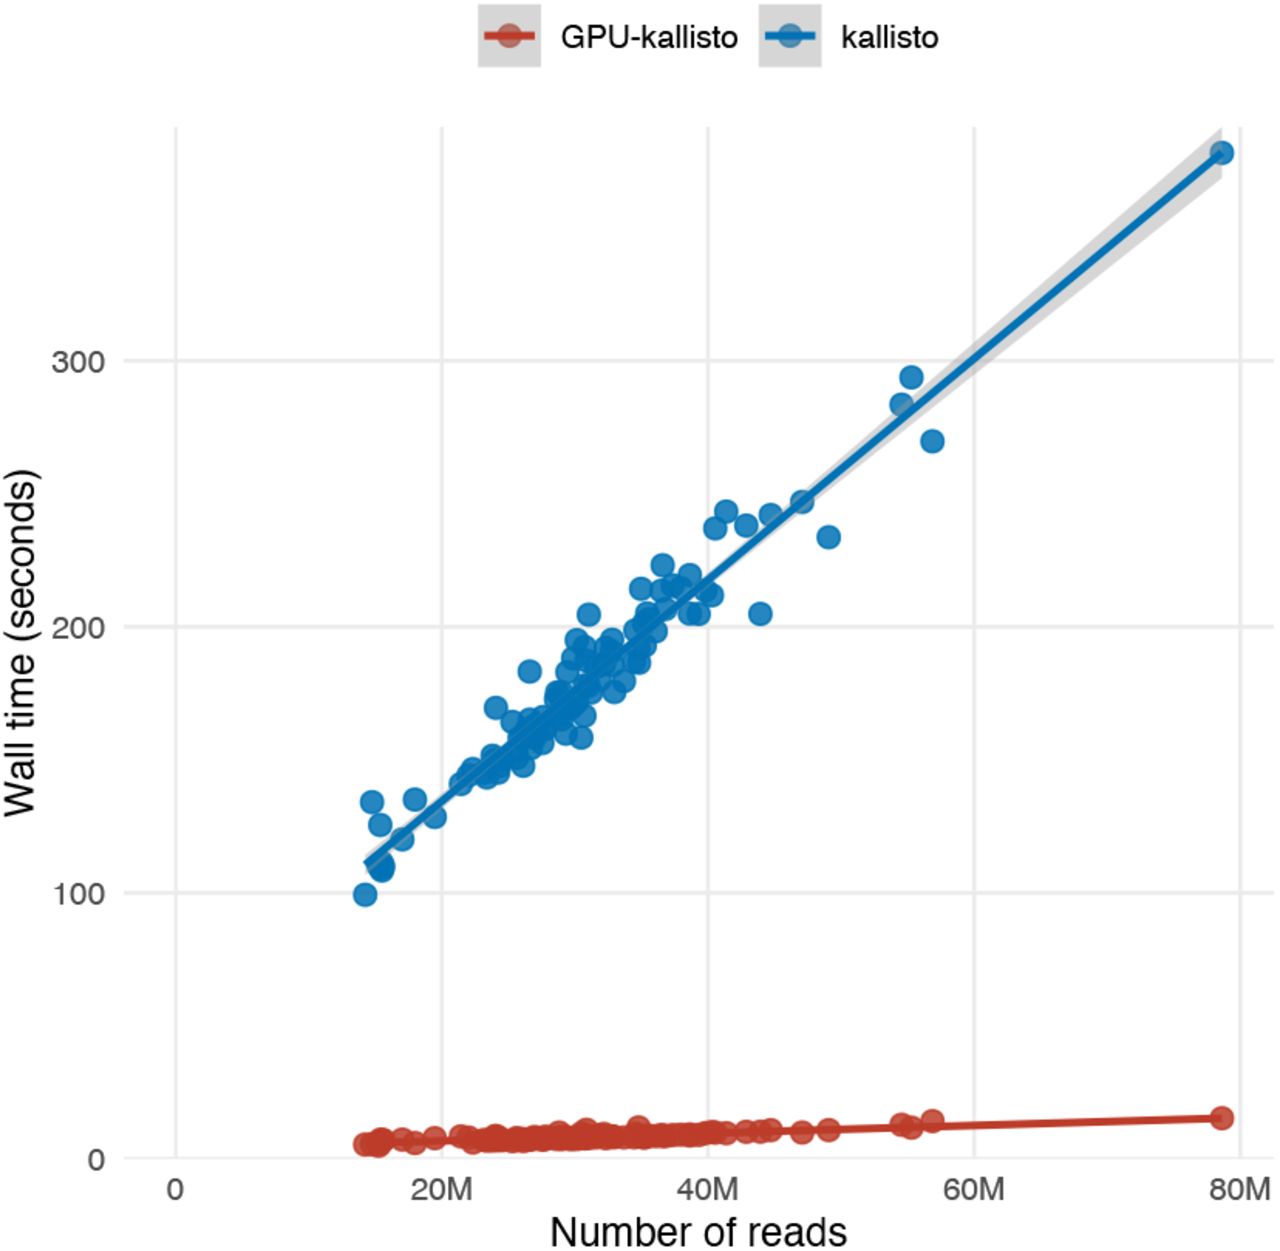
<p>In the March 2026 preprint <a href="https://www.biorxiv.org/content/10.64898/2026.03.04.709526v1.full.pdf">RNA-seq analysis in seconds using GPUs</a>, Páll Melsted, a coauthor of the original kallisto paper, joins Elís Mar Guðnýjarson and Jóhannes Nordal in redesigning pseudoalignment, equivalence-class intersection, and EM for NVIDIA GPUs. Across 100 Geuvadis RNA-seq samples, they report about a 30× speedup when setup is excluded. For a dataset containing 295 million paired-end reads, runtime falls from about 40 minutes with 16 CPU threads to 50 seconds on the GPU.</p>

<p>Their benchmark results are reproduced below:</p>

<figure class="k-paper-figure k-paper-benchmark" id="gpu-benchmark">
  <a href="/images/kallisto/figure-1-benchmark.jpg" aria-label="Open the original benchmark plot at full size">
    <img src="/images/kallisto/figure-1-benchmark.jpg" width="1280" height="1251" loading="lazy" alt="Wall time versus sample read count for 100 Geuvadis samples. CPU kallisto times rise from about 100 to 380 seconds; GPU kallisto times remain below about 20 seconds across the plotted range." />
  </a>
  <figcaption>Figure 1 from <a href="https://doi.org/10.64898/2026.03.04.709526">Melsted, Guðnýjarson, and Nordal (2026)</a>.</figcaption>
</figure>

<p>The benchmark used an RTX 5090 with 32 GB of GPU memory, a Ryzen 9 9900X, NVMe storage, and BGZF-compressed input. BGZF divides compressed data into independent blocks, allowing several blocks to be decompressed on the GPU at once; ordinary gzip remains serial and is decompressed on the CPU.</p>

<h3 id="how-they-implement-it-k-mers-and-em-in-parallel">How they implement it: k-mers and EM in parallel</h3>

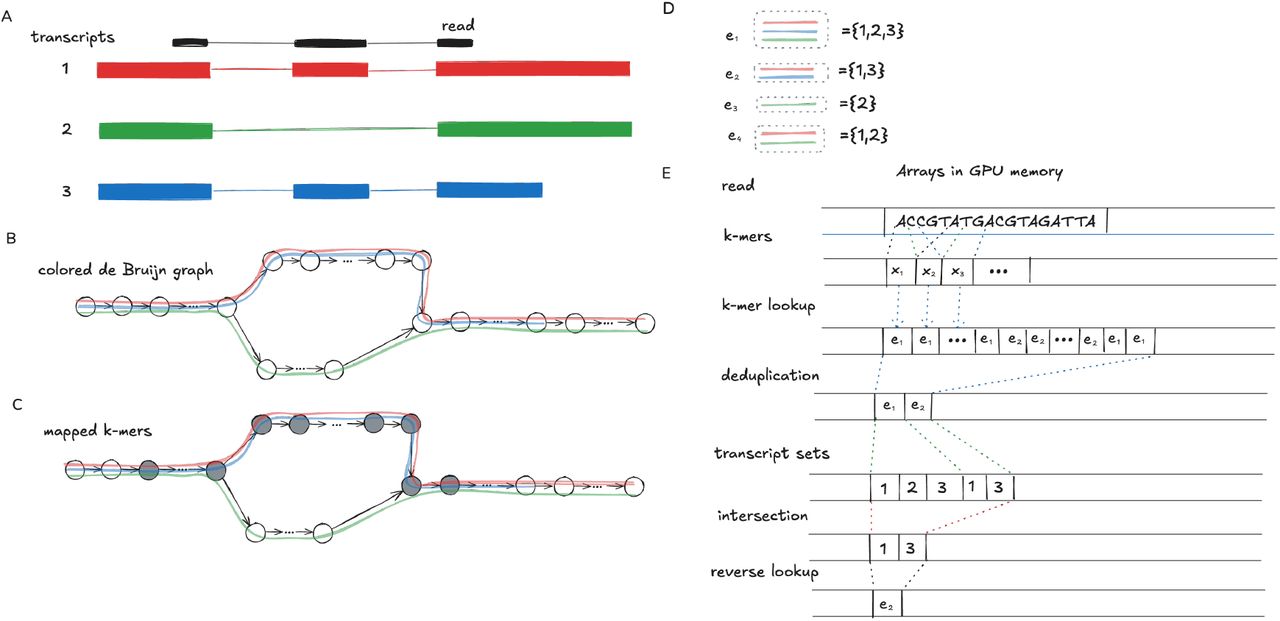
<p>The transcript index is moved into GPU memory. Each k-mer is encoded as a 64-bit integer and looked up in a GPU hash table to obtain an equivalence-class ID. Transcript sets are stored in one flattened array with offsets marking where each set begins. Threads generate and look up k-mers from many reads concurrently, remove repeated and empty candidate sets, intersect the remaining transcript lists, and look up the resulting equivalence class.</p>

<p>The intersections have different sizes, so their memory requirements are not known in advance. The implementation first estimates how much temporary space each read needs, uses a parallel prefix scan to assign each thread a nonoverlapping slice of memory, and then performs the intersections in a second pass. This two-pass design replaces the convenient per-read dynamic allocation that a CPU implementation might use.</p>

<figure class="k-paper-figure" id="gpu-pipeline">
  <a href="/images/kallisto/figure-2-pipeline.jpg" aria-label="Open the original GPU pipeline diagram at full size">
    <img src="/images/kallisto/figure-2-pipeline.jpg" width="1280" height="621" loading="lazy" alt="Panels A to D connect three transcripts, their colored de Bruijn graph, read k-mer matches, and transcript sets. Panel E follows GPU arrays through k-mer lookup, deduplication, transcript-set intersection, and reverse lookup of the resulting class." />
  </a>
  <figcaption>Figure 2 from <a href="https://doi.org/10.64898/2026.03.04.709526">Melsted et al. (2026)</a>.</figcaption>
</figure>

<p>EM uses a second layout: a transposed index records, for each transcript, every equivalence class containing it. During the E-step, the GPU first calculates the denominator for every class in parallel. It then uses the transposed index to sum class contributions for every transcript in parallel. The M-step normalizes those transcript totals, and the implementation checks convergence every ten iterations. This is the same E-step and M-step from Experiment 3, reorganized so that a single iteration can occupy the GPU.</p>

<p>Implementation details are available in the <a href="https://github.com/pachterlab/kallisto/tree/gpu">kallisto GPU branch</a>.</p>

<h3 id="what-is-the-bottleneck-now">What is the bottleneck now?</h3>

<p>The paper reports a mapping rate of 24.1 million read pairs per second, but an end-to-end rate of about 3.6 million pairs per second. In its average timing breakdown, GPU mapping takes 722 ms while EM takes 3,148 ms. I/O and decompression use another 841 ms of GPU time plus 2,370 ms of CPU time. Once k-mer lookup becomes this fast, it is no longer the main constraint.</p>

<figure class="k-paper-figure" id="gpu-runtime">
  <a href="/images/kallisto/table-1-runtime.png" aria-label="Open the original runtime table at full size">
    <img src="/images/kallisto/table-1-runtime.png" width="2190" height="460" loading="lazy" alt="Table 1: average component runtimes across 100 Geuvadis samples. CPU and GPU times respectively: index setup 376 and 933 ms; I/O and decompression 2370 and 841 ms; GPU mapping 514 and 722 ms; EM has no CPU time listed and 3148 ms GPU time." />
  </a>
  <figcaption>Table 1 from <a href="https://doi.org/10.64898/2026.03.04.709526">Melsted et al. (2026)</a>. The CPU and GPU columns report work within the GPU implementation, rather than two separate implementations.</figcaption>
</figure>

<p>This result shifts the research question from “Can kallisto run on a GPU?” to <strong>Should the saved computation be used to obtain richer evidence, rather than only to reduce runtime?</strong> If pseudoalignment is no longer expensive, selected ambiguous fragments could receive additional alignment or sequence-error scoring before abundance estimation. This possibility leads directly to reconsidering Bowtie 2 and RSEM below.</p>

<h2 id="bowtie2-rsem">8. Research direction: revisit Bowtie 2 + RSEM on GPUs</h2>

<p>The GPU result suggests a broader question: <strong>if pseudoalignment is now extremely fast, is discarding alignment detail still the best accuracy–runtime tradeoff?</strong> kallisto keeps candidate-transcript sets, whereas <a href="https://pmc.ncbi.nlm.nih.gov/articles/PMC3322381/">Bowtie 2</a> preserves base-level alignment evidence and <a href="https://bmcbioinformatics.biomedcentral.com/articles/10.1186/1471-2105-12-323">RSEM</a> uses that evidence to estimate expression. Modern GPUs may make it practical to retain more information without returning to the runtimes that originally motivated pseudoalignment.</p>

<p>Bowtie 2 + RSEM was a strong accuracy baseline in the original kallisto comparison, but that does not establish it as universally more accurate. Later work also shows that <a href="https://genomebiology.biomedcentral.com/articles/10.1186/s13059-020-02151-8">mapping methodology affects abundance accuracy on real data</a>. The research question is therefore whether richer alignment evidence improves transcript estimates enough to justify its remaining computational cost, particularly for rare and highly ambiguous isoforms.</p>

<p>A rough study would have three stages. First, accelerate Bowtie 2–compatible alignment while preserving the paired-end relationships, alignment scores, and record formats that <a href="https://github.com/deweylab/RSEM#using-an-alternative-aligner">RSEM requires</a>. Second, parallelize RSEM’s abundance estimation without changing its statistical model. Third, compare this pipeline with GPU kallisto on the same references and RNA-seq libraries, measuring end-to-end runtime, memory use, and gene- and transcript-level accuracy using both simulated truth and independent experimental evidence. The result would test whether modern hardware changes which information should be retained for transcript quantification.</p>

<h2 id="conclusion">9. Conclusion: two research directions</h2>

<p>kallisto became fast by asking only which transcripts are compatible with each fragment, compressing repeated candidate sets into equivalence-class counts, and applying EM to estimate abundance. The experiments in this article expose both sides of that design: compression makes computation efficient, but shared fragments can remain unresolved, and EM still requires repeated updates.</p>

<p>Two research directions follow from this tension:</p>

<ul>
  <li><strong>Learn the abundance calculation.</strong> A neural surrogate could operate on the graph connecting equivalence classes and transcripts, learning several EM-like updates or directly approximating the converged abundance estimate. This direction asks whether the repeated computation can be learned while preserving the likelihood objective and correct behavior when the evidence is ambiguous.</li>
  <li><strong>Retain richer evidence with GPU computing.</strong> A GPU implementation of Bowtie 2 + RSEM could preserve alignment locations, scores, mismatches, and paired-end constraints that pseudoalignment omits. This direction asks whether modern hardware can make a more detailed statistical model competitive in runtime and more informative for rare or ambiguous isoforms.</li>
</ul>

<p>These directions spend computation differently. One learns a faster solver after the evidence has been compressed; the other keeps richer evidence and accelerates the full pipeline. Testing both on the same data would show whether the next improvement comes from faster inference, better evidence, or both.</p>

<h2 id="references">10. References</h2>

<ol class="k-references">
  <li>Bray, N. L., Pimentel, H., Melsted, P., and Pachter, L. (2016). <a href="https://doi.org/10.1038/nbt.3519">Near-optimal probabilistic RNA-seq quantification</a>. <em>Nature Biotechnology</em>, 34, 525–527.</li>
  <li>Pachter Lab. <a href="https://pachterlab.github.io/kallisto/manual">kallisto manual</a>.</li>
  <li>Li, Z., Kovachki, N., Azizzadenesheli, K., Liu, B., Bhattacharya, K., Stuart, A., and Anandkumar, A. (2021). <a href="https://arxiv.org/abs/2010.08895">Fourier Neural Operator for Parametric Partial Differential Equations</a>. <em>International Conference on Learning Representations</em>.</li>
  <li>Greff, K., van Steenkiste, S., and Schmidhuber, J. (2017). <a href="https://papers.neurips.cc/paper/7246-neural-expectation-maximization">Neural Expectation Maximization</a>. <em>Advances in Neural Information Processing Systems</em>, 30.</li>
  <li>Zhou, L., Shakeri, F., Sadraoui, A., Kaaniche, M., Pesquet, J.-C., and Ben Ayed, I. (2025). <a href="https://openaccess.thecvf.com/content/CVPR2025/html/Zhou_UNEM_UNrolled_Generalized_EM_for_Transductive_Few-Shot_Learning_CVPR_2025_paper.html">UNEM: UNrolled Generalized EM for Transductive Few-Shot Learning</a>. <em>Proceedings of CVPR</em>, 9665–9675.</li>
  <li>Melsted, P., Guðnýjarson, E. M., and Nordal, J. (2026). <a href="https://doi.org/10.64898/2026.03.04.709526">RNA-seq analysis in seconds using GPUs</a>. <em>bioRxiv</em>, version 1.</li>
  <li>Pachter Lab. <a href="https://github.com/pachterlab/kallisto/tree/gpu">GPU branch of kallisto</a>. Source code accompanying Melsted et al. (2026).</li>
  <li>Langmead, B., and Salzberg, S. L. (2012). <a href="https://doi.org/10.1038/nmeth.1923">Fast gapped-read alignment with Bowtie 2</a>. <em>Nature Methods</em>, 9, 357–359.</li>
  <li>Li, B., and Dewey, C. N. (2011). <a href="https://doi.org/10.1186/1471-2105-12-323">RSEM: accurate transcript quantification from RNA-Seq data with or without a reference genome</a>. <em>BMC Bioinformatics</em>, 12, 323. See also the <a href="https://github.com/deweylab/RSEM#using-an-alternative-aligner">RSEM alignment requirements</a>.</li>
  <li>Srivastava, A., Malik, L., Sarkar, H., Zakeri, M., Almodaresi, F., Soneson, C., Love, M. I., Kingsford, C., and Patro, R. (2020). <a href="https://doi.org/10.1186/s13059-020-02151-8">Alignment and mapping methodology influence transcript abundance estimation</a>. <em>Genome Biology</em>, 21, 239.</li>
</ol>

<script defer="" src="/assets/kallisto/vendor/katex-0.18.7/katex.min.js"></script>

<script defer="" src="/assets/kallisto/math.js"></script>

<script defer="" src="/assets/kallisto/model.js"></script>

<script defer="" src="/assets/kallisto/playground.js"></script>]]></content><author><name></name></author><summary type="html"><![CDATA[Change an RNA-seq read, follow its k-mers, and watch kallisto estimate transcript abundance. Explore how kallisto works, what its estimates mean, and what GPUs can make faster.]]></summary></entry><entry><title type="html">ICML2025 Video-Related Research</title><link href="https://dianyo.github.io/ICML2025-Video-Related-Research/" rel="alternate" type="text/html" title="ICML2025 Video-Related Research" /><published>2025-07-30T00:00:00+00:00</published><updated>2025-07-30T00:00:00+00:00</updated><id>https://dianyo.github.io/ICML2025-Video-Related-Research</id><content type="html" xml:base="https://dianyo.github.io/ICML2025-Video-Related-Research/"><![CDATA[<p>In this post, I’ll quickly summarize the video generation related research that I found interesting in ICML2025.</p>

<h2 id="xattention-block-sparse-attention-with-antidiagonal-scoring">XAttention: Block Sparse Attention with Antidiagonal Scoring</h2>

<h3 id="problem">Problem</h3>
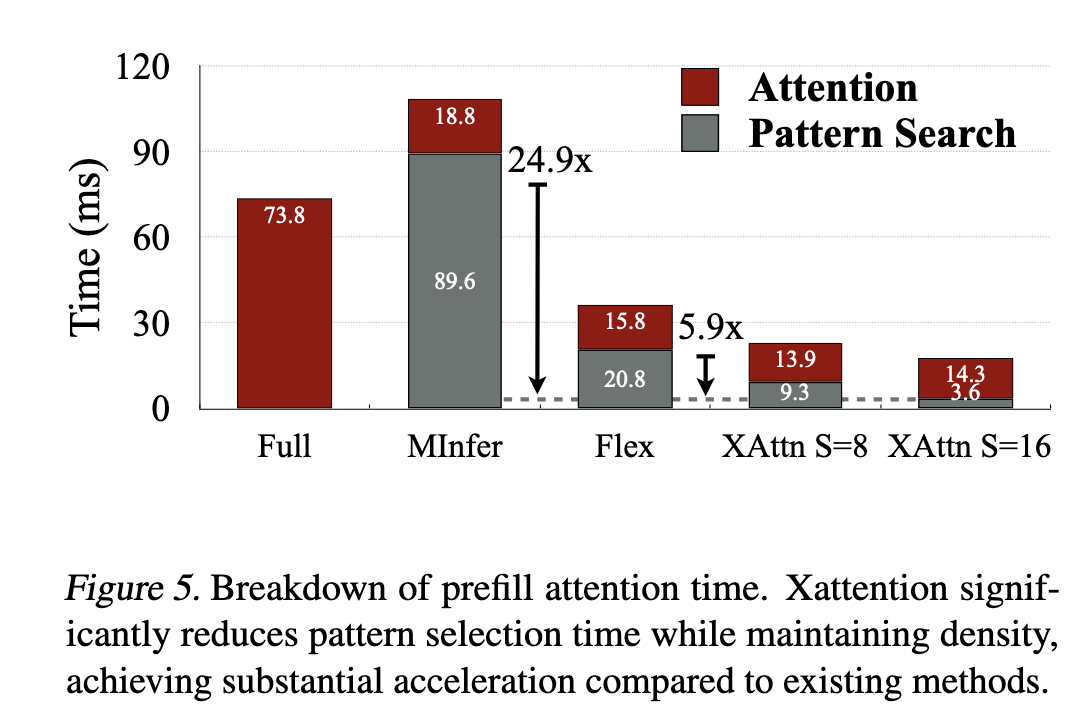
<p>Existing block-sparse methods have struggled to deliver on their full potential of orginal models, often grappling with a trade-off between accuracy and efficiency, where the efficiency is also limited by importance score searching. <strong>Can we design a block-sparse attention mechanism that dramatically accelerates longcontext Transformers without compromising accuracy, truly unlocking their potential for real-world applications?</strong></p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/XAttn_search_compare.png" alt="XAttn_search_compare" />
</div>

<h3 id="proposed-method">Proposed Method</h3>
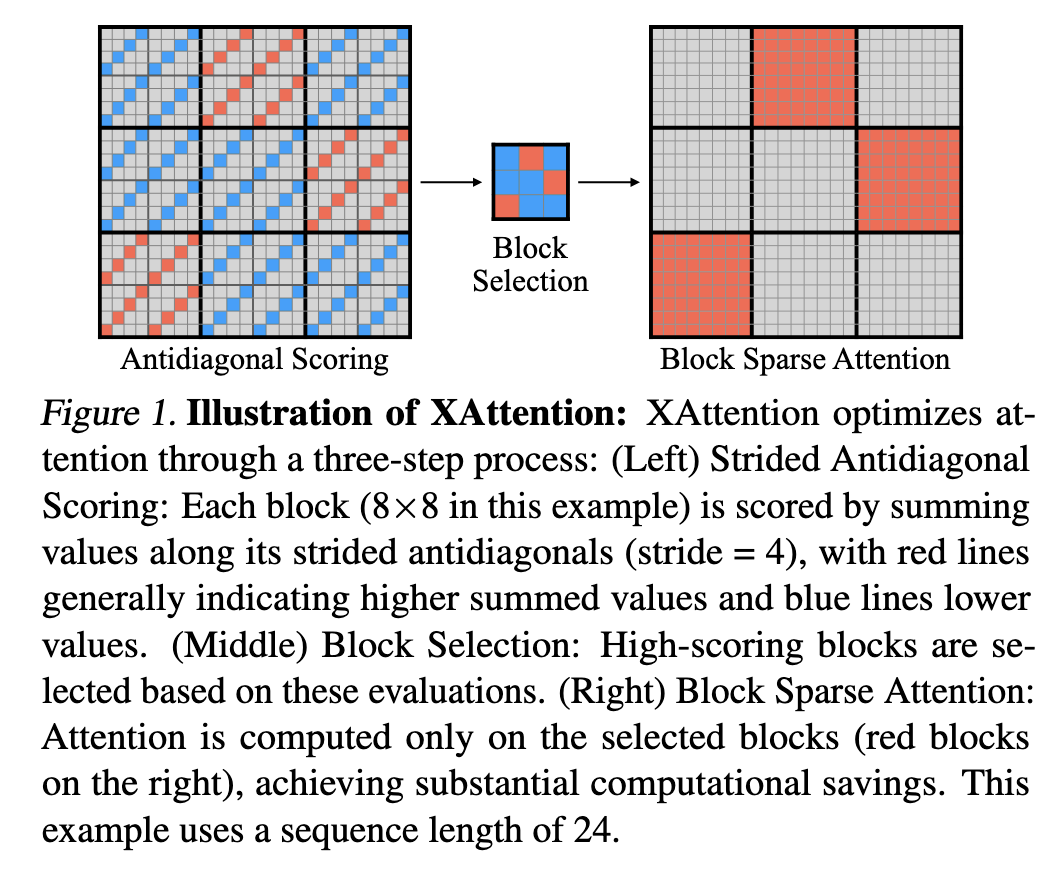
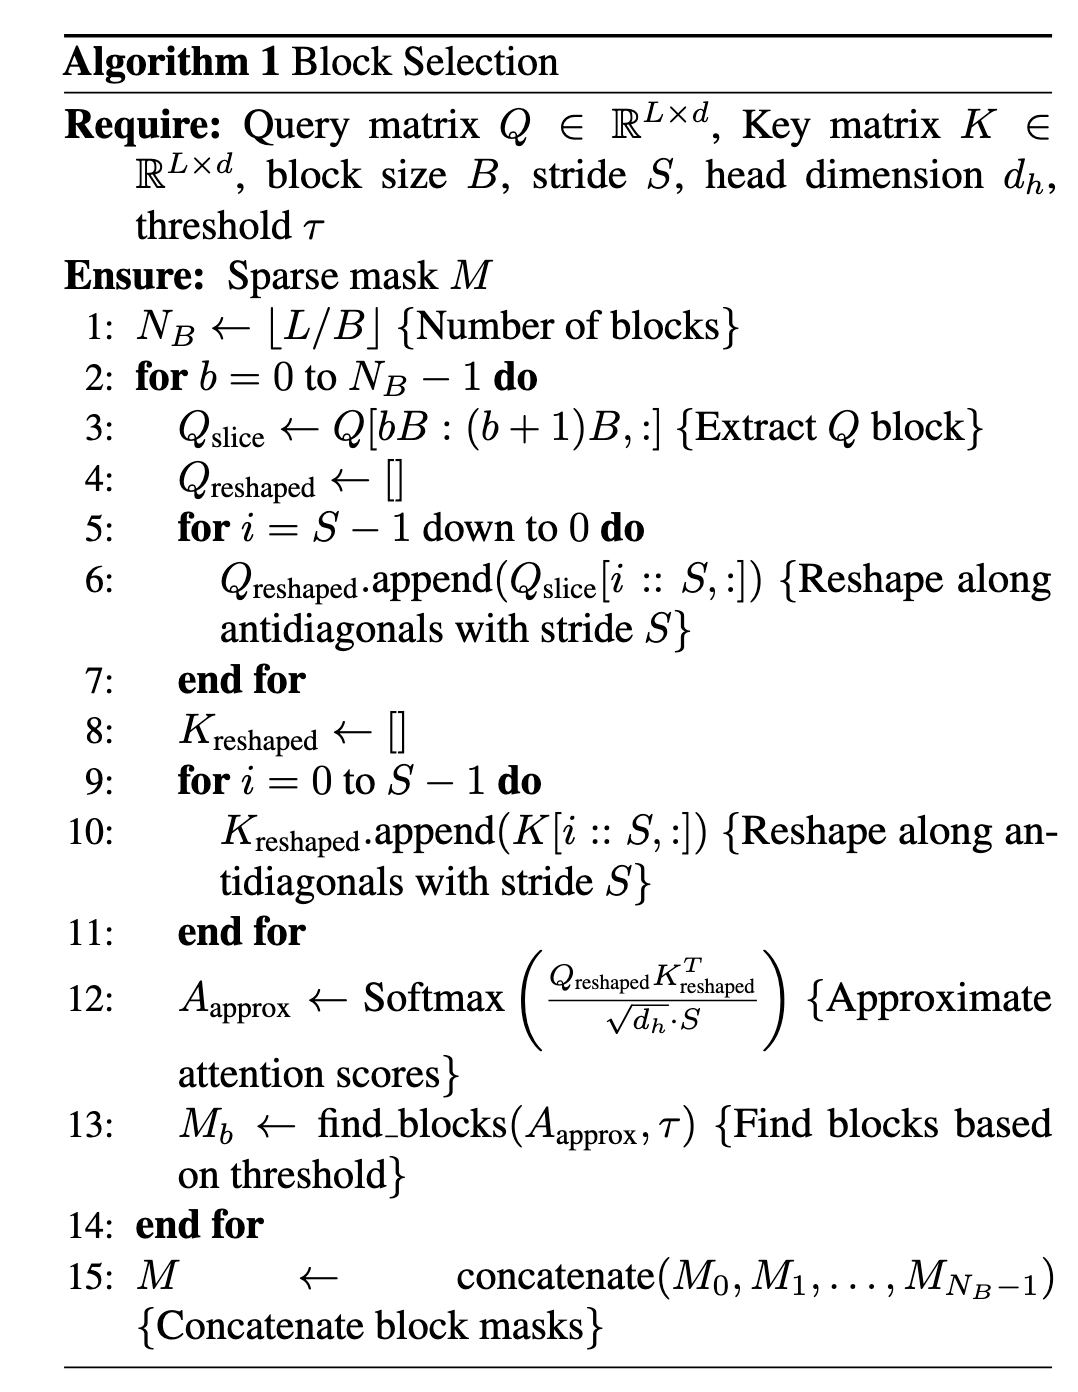
<p>The authors propose a new block-sparse attention mechanism, XAttention, that leverages antidiagonal scoring to achieve high accuracy while maintaining efficiency by their empirical observations though they didn’t mention a lot of how they find this observation. Other than the block selection by a threshold, the authors also propose a dynamic threshold prediction method using dynamic programming to set the threshold for each block but which is not mandatory.</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/XAttn_fig.png" alt="XAttention" style="width: 48%; display: inline-block;" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/XAttn_algo.png" alt="XAttention algorithm" style="width: 48%; display: inline-block;" />
</div>

<h3 id="experiments--results">Experiments &amp; Results</h3>

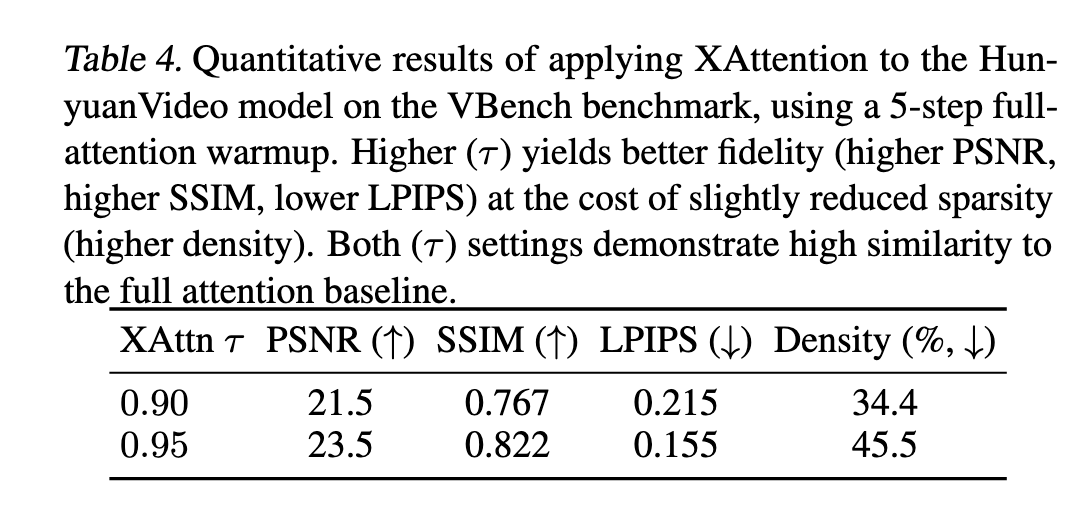
<p>As the XAttention is focus on prefill stage of the Transformer, it can be applied to any Transformer-based models. We only show the results on video generation task using HunyuanVideo here, but the authors also show the results on other tasks like NLP using Llama-3.18B-Instruc and video understanding using Qwen2-VL-7B-Instruct. Authors choose 946 GPT-augmented text prompts from VBench for video generation task, and use full attention as the baseline as the above mentioned methods are all applied to casual attention.</p>

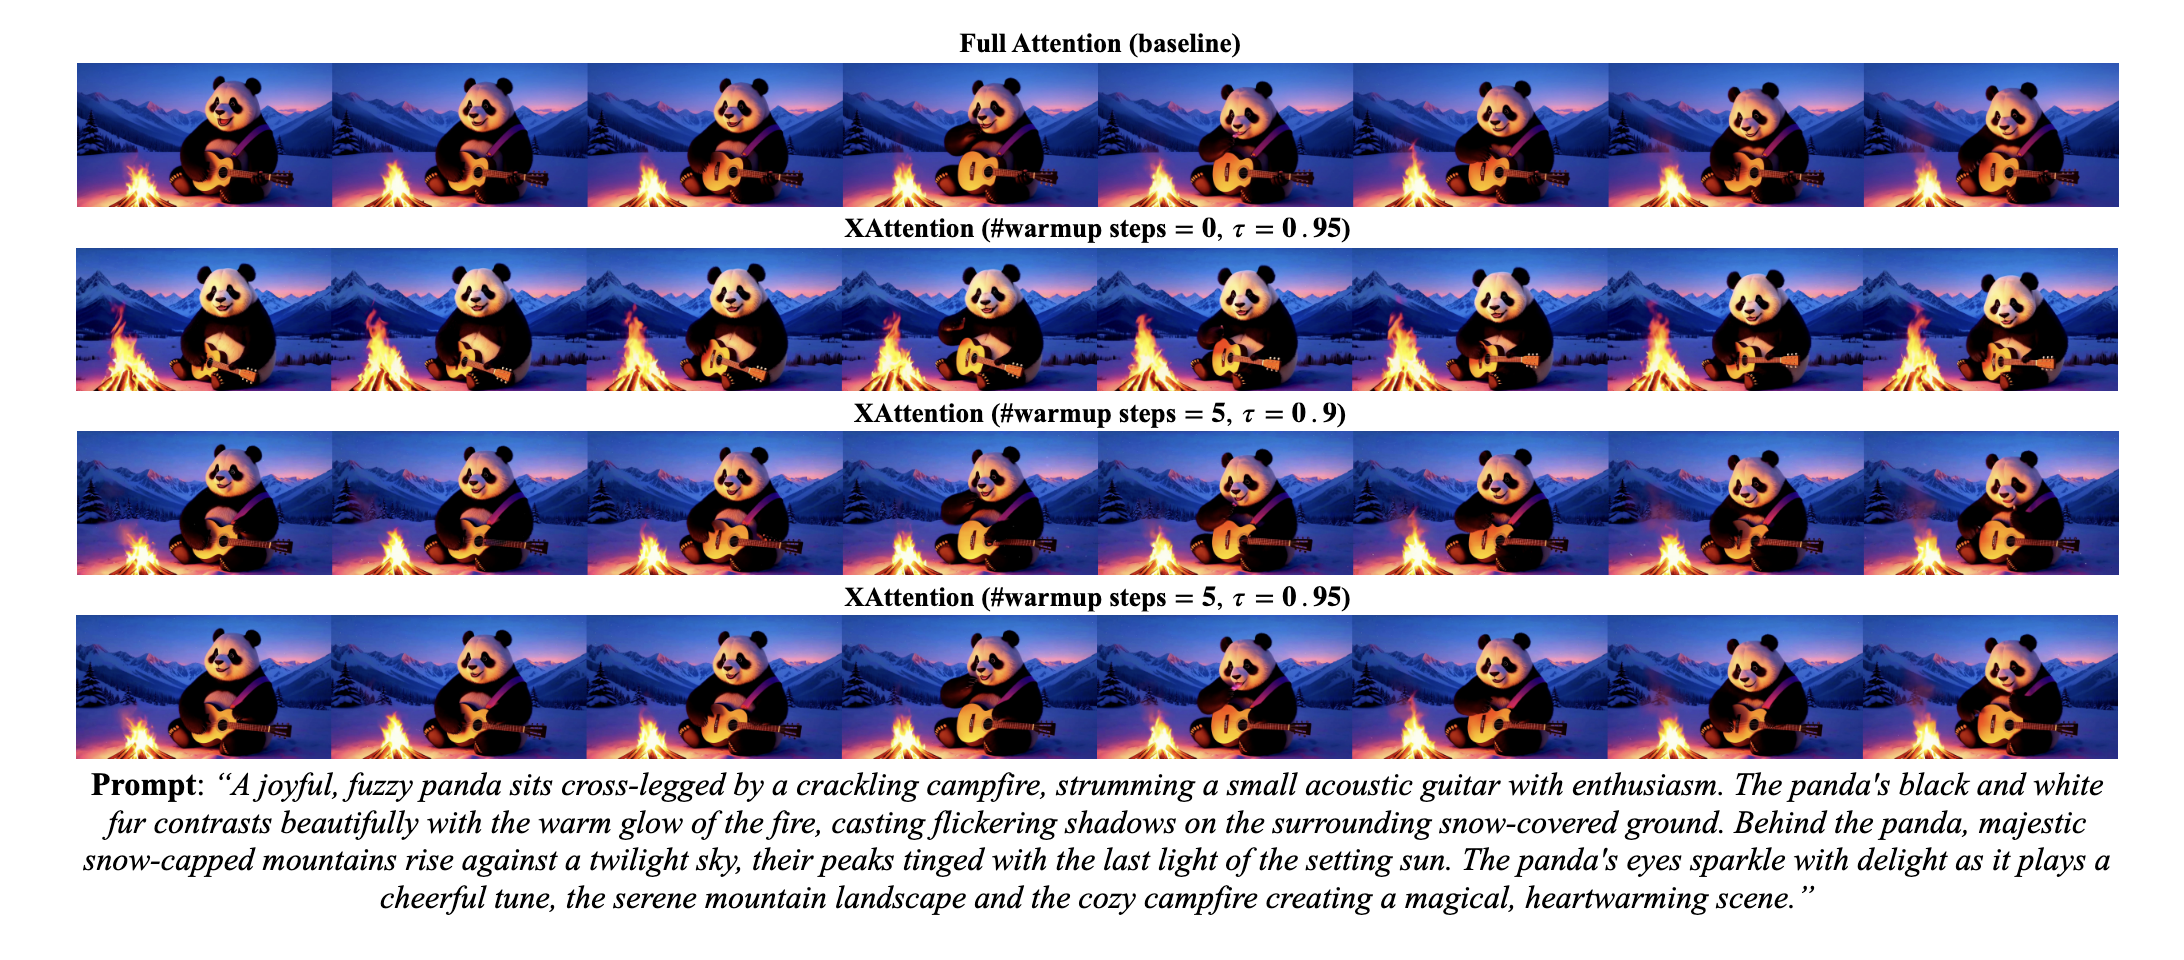
<p>Authors found that applying XAttention from the very beginning of the denoising process in the HunyuanVideo model led to slight layout shifts, that they decided to introduce a 5-step “warmup” stage as research shows early denoising steps are critical for determining content layout. The reults shows more than 50% sparsity can be achieved after applying XAttention, however they didn’t provide the speedup numbers directly.</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/XAttn_video_warmup.png" alt="XAttn_warmup" />
</div>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/XAttn_video_table.png" alt="XAttn_results" />
</div>

<h2 id="conceptattention-diffusion-transformers-learn-highly-interpretable-features">ConceptAttention: Diffusion Transformers Learn Highly Interpretable Features</h2>

<h3 id="problem-1">Problem</h3>
<p>The understanding of the internal mechanisms of diffusion models is limited, and the decision-making process of diffusion models is not interpretable. The rapid advancement and enhanced capabilities of DiT-based models highlight the critical importance of methods that improve their interpretability, transparency, and safety.</p>

<h3 id="proposed-method-1">Proposed Method</h3>
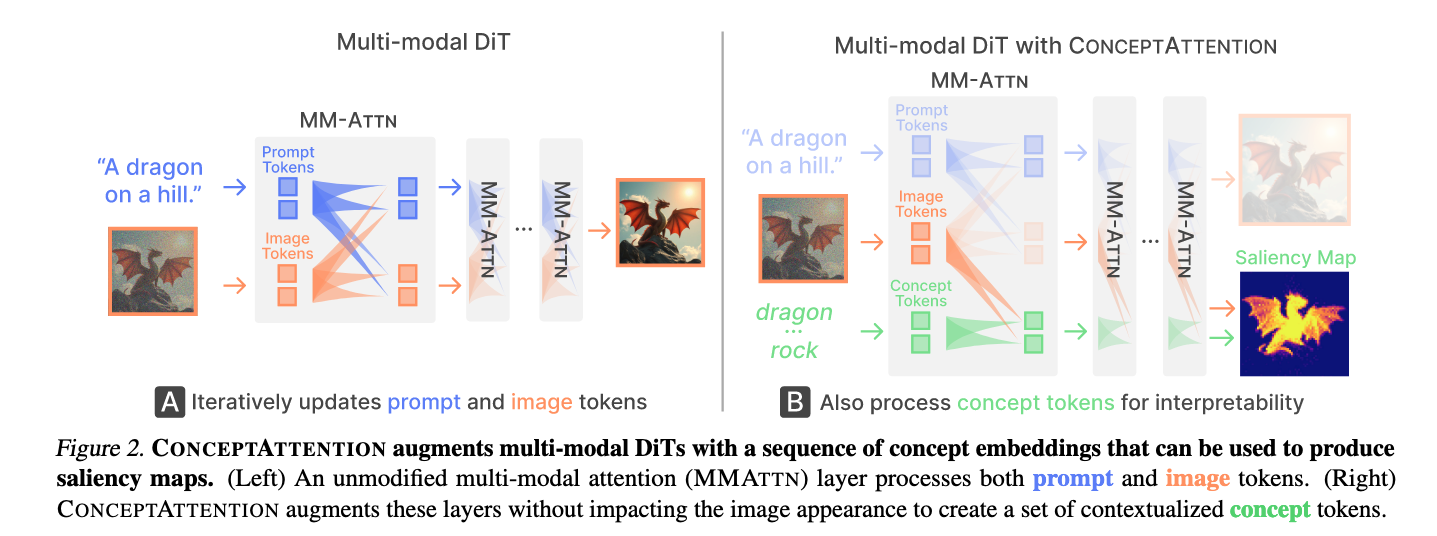
<p>ConceptAttention utilize the multi-modal attention layers (MMATTN) in DiT to generate high quality saliency maps that depict the location of the input textual concepts in generated images. The authors create a set of contextualized concept embeddings for textual concepts and use them alongside the original input image and text, the concept input will do cross-attention with the image and self-attention with itself cause the authors found that performing both instead of just cross-attention improves the donwstream tasks performance. The concept branch won’t affect the orignal generation process. The high level idea is shown in the following figure</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_fig.png" alt="ConceptAttention" />
</div>

<p>The detail algorithm is composed by the following fomulas, where subscripts ( x ) denotes image, ( p ) denotes text input prompt, ( c ) denotes concept input.</p>

<div style="text-align: center; width: 60%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_formula4.png" alt="ConceptAttention formula 4" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_formula5.png" alt="ConceptAttention formula 5" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_formula6.png" alt="ConceptAttention formula 6" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_formula7.png" alt="ConceptAttention formula 7" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_formula8.png" alt="ConceptAttention formula 8" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_formula9_10.png" alt="ConceptAttention formula 9 &amp; 10" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_formula11.png" alt="ConceptAttention formula 11" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_formula_sum.png" alt="ConceptAttention formula final" />
</div>

<h3 id="experiments--results-1">Experiments &amp; Results</h3>
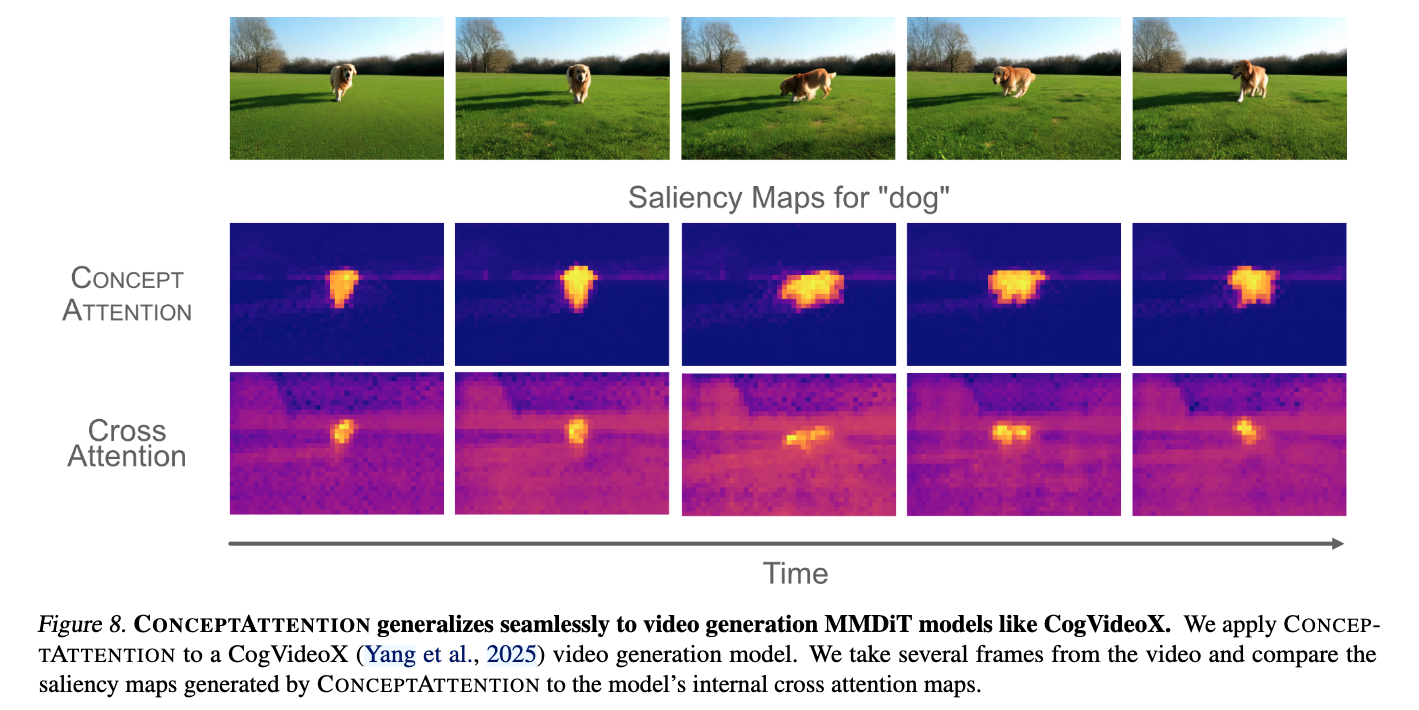
<p>Most of the experiments are conducted on image generation task, but author shows in one case that ConceptAttention can also be applied to video generation task on CogVideoX, where they further average over the frame dimension to get the final saliency map.</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_video_result.png" alt="ConceptAttention video results" />
</div>

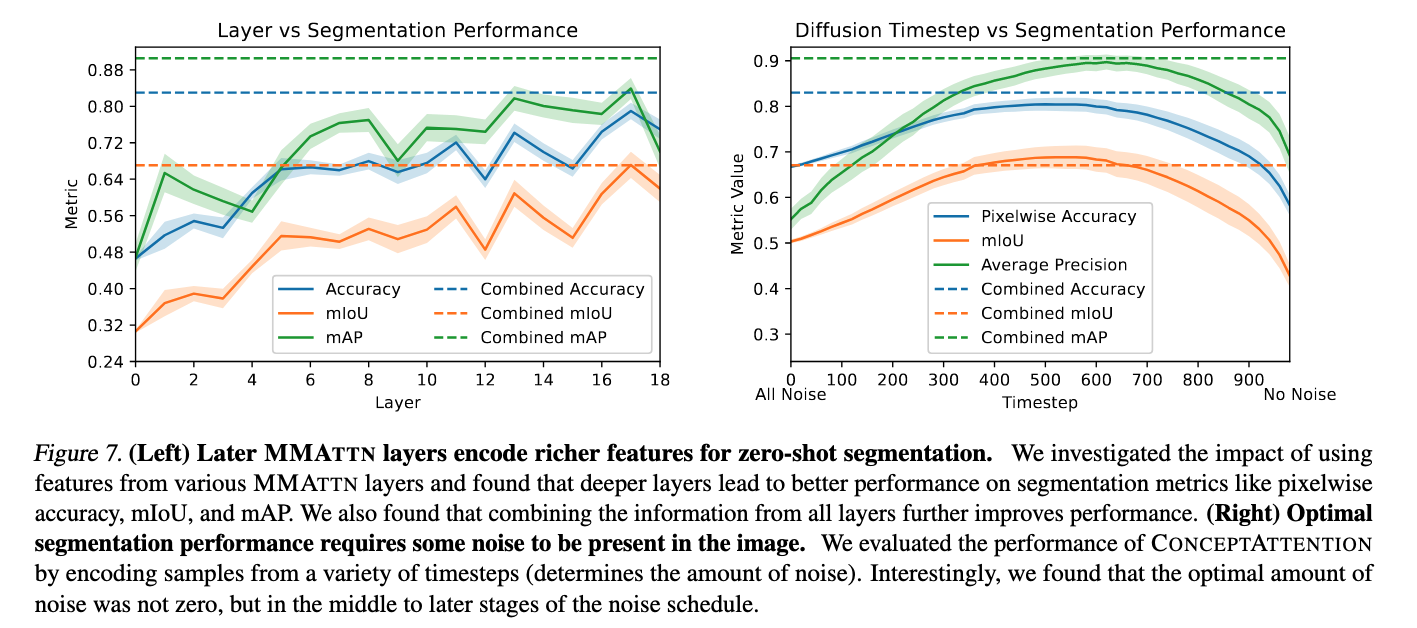
<p>The authors also provide a inspiring ablation study on how different the output concept various between diffusion steps and DiT layers. The layers is more intuitive that the deeper layers have more refined representation that better transfer to the segmentation task. However, for the diffusion steps, it’s surprising that although the later timesteps is less noisy, the concpet output is the best at the middle of the diffusion process.</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/ConceptAttn_ablation.png" alt="ConceptAttention ablation" />
</div>

<h2 id="spare-videogen-accelerating-video-diffusion-transformers-with--spatial-temporal-sparsity">Spare VideoGen: Accelerating Video Diffusion Transformers with  Spatial-Temporal Sparsity</h2>

<h3 id="problem-2">Problem</h3>
<p>Video geneartion is computationally expensive, and due to the quadratic computational complexity with respect to context length, in video it’s resolution and number of frames, the computational cost is even more expensive. (General video generation issue nowadays). <strong>How to leverage the nature of attention sparsity that has been shown to be effective in language models to accelerate the video generation process?</strong></p>

<h3 id="observation--proposed-method">Observation &amp; Proposed Method</h3>
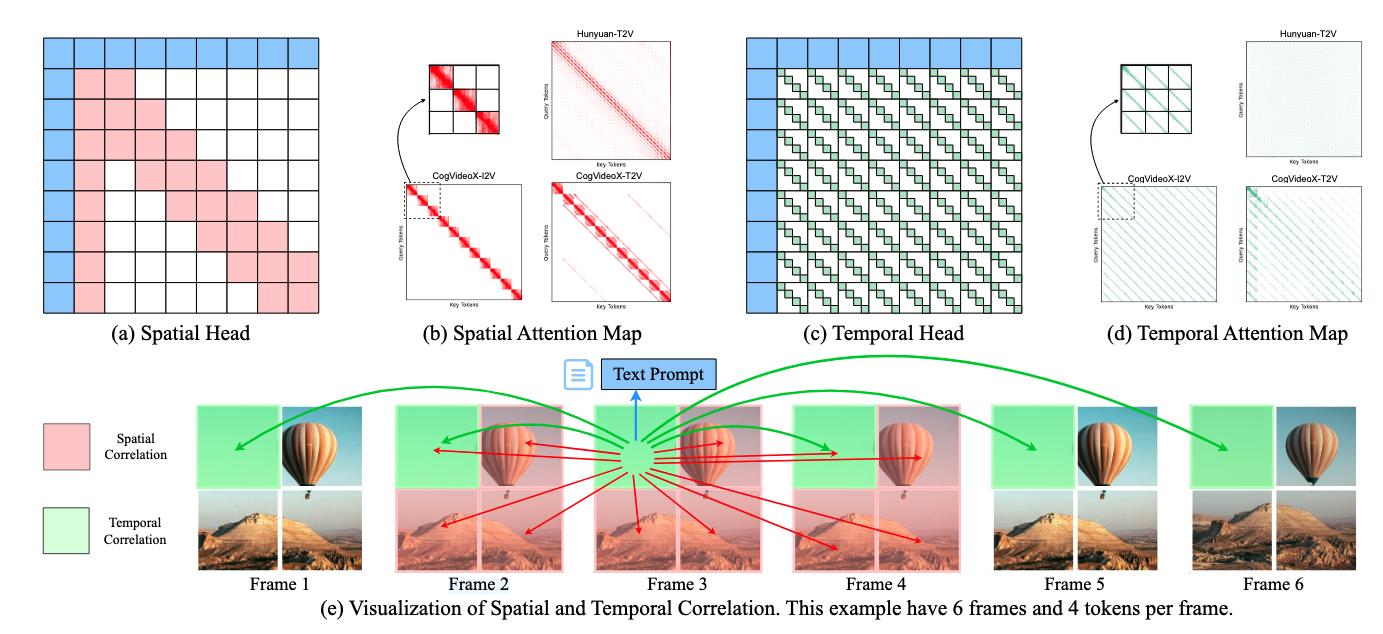
<p>The author observes two inherent sparsity attention patterns, spatial head sparsity and temporal head sparsity. The spatial head sparsity is caused by the model attention is more focused on the local region, while the temporal head sparsity is cuased by the model look at similar regions across frames. Besides, the authors also found that the text prompt and the first frame hold significant attention scores for both spatial and temporal head, so the include these tokens in both spatial and temporal head.</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/SVG_spatial_temporal_head.png" alt="SpareVideoGen" />
</div>

<p>The authors further propose a method to leverage the above nature of attention sparsity called Sparse VideoGen (SVG), which is composed by two parts: (1) An online profiling strategy to identify the best sparsity pattern for each head, (2) A layout transformation, which reorders the noncontiguous sparsity pattern of temporal heads to make it hardware friendly.</p>

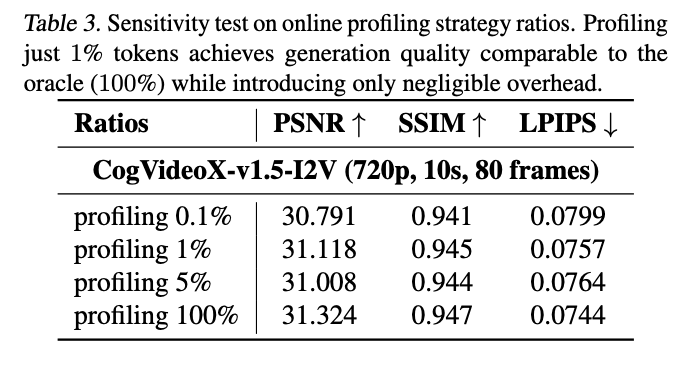
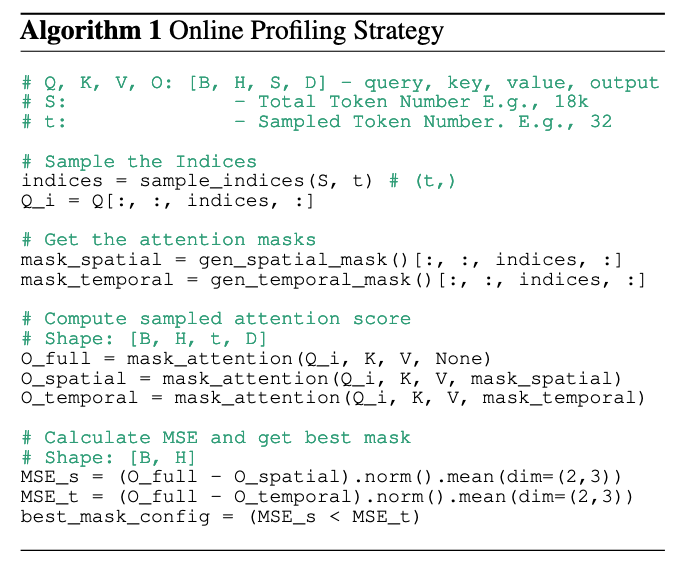
<p>The main reason that we need online profiling here is that the sparse pattern is highly dynamic across different denoising steps and input data. The proposed online profiling strategy is first sampling a subset of input rows then calculates results with both the spatial and temporal sparsity patterns, and then select the sparsity pattern that has the lower MSE compared to full attention. Profiling just 1% tokens is enough to achieve good results compared to oracle (100%).</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/SVG_online_strategy_ablation.png" alt="SVG online profiling" style="width: 48%; display: inline-block;" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/SVG_online_strategy_algo.png" alt="SVG online profiling algorithm" style="width: 48%; display: inline-block;" />
</div>

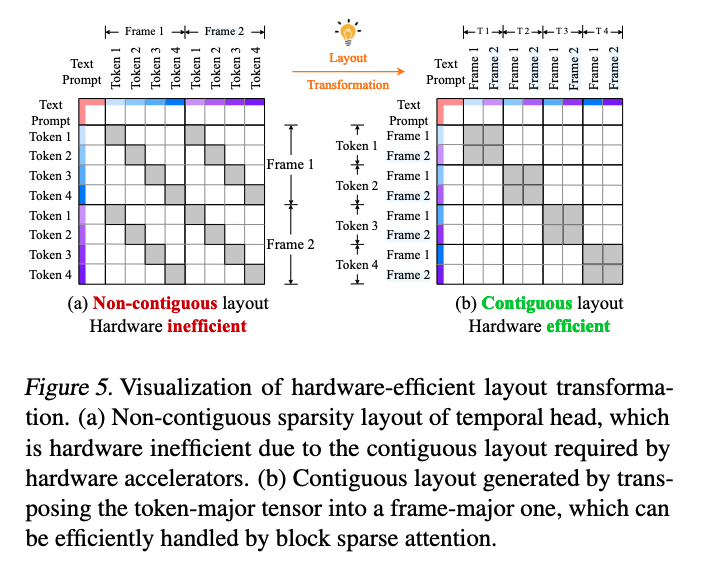
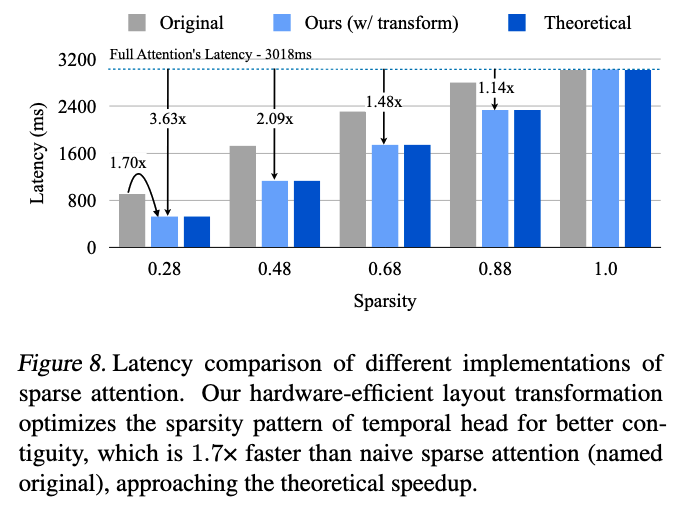
<p>Because of the hardware limitation, for exmaple NVIDIA’s Tensor Core required at least 16 contiguous elements along each dimenstion to best utilize the hardware, and the temporal head exhibits a sparse layout of non-contiguous elements with a stride of ( L ) (the number of tokens per frame), SVG propose a layout transformation strategy from token major to frame major as follows:</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/SVG_layout_transformation.png" alt="SVG layout transformation" />
</div>

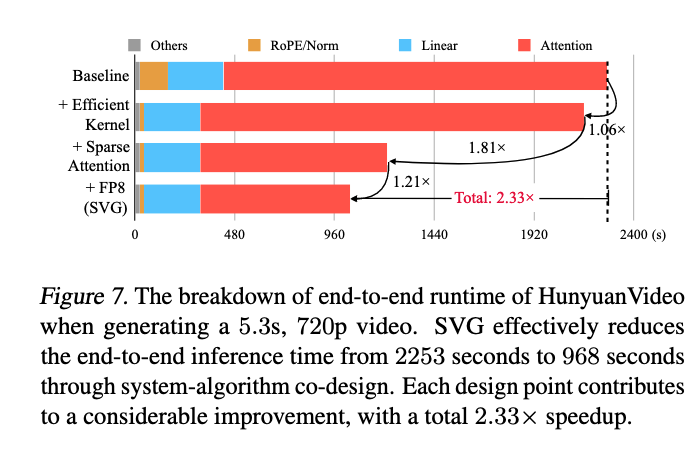
<p>Some details: QK-norm and RoPE is customized with CUDA acode by a sub-warp reduction implementation. The online profiling strategy (fused) and the layout transformation are impelmented by Triton kernel, while the sparse attention kernel using FlashInfer. The authors also implement FP8 quantization into sparse attention.</p>

<h3 id="experiments--results-2">Experiments &amp; Results</h3>
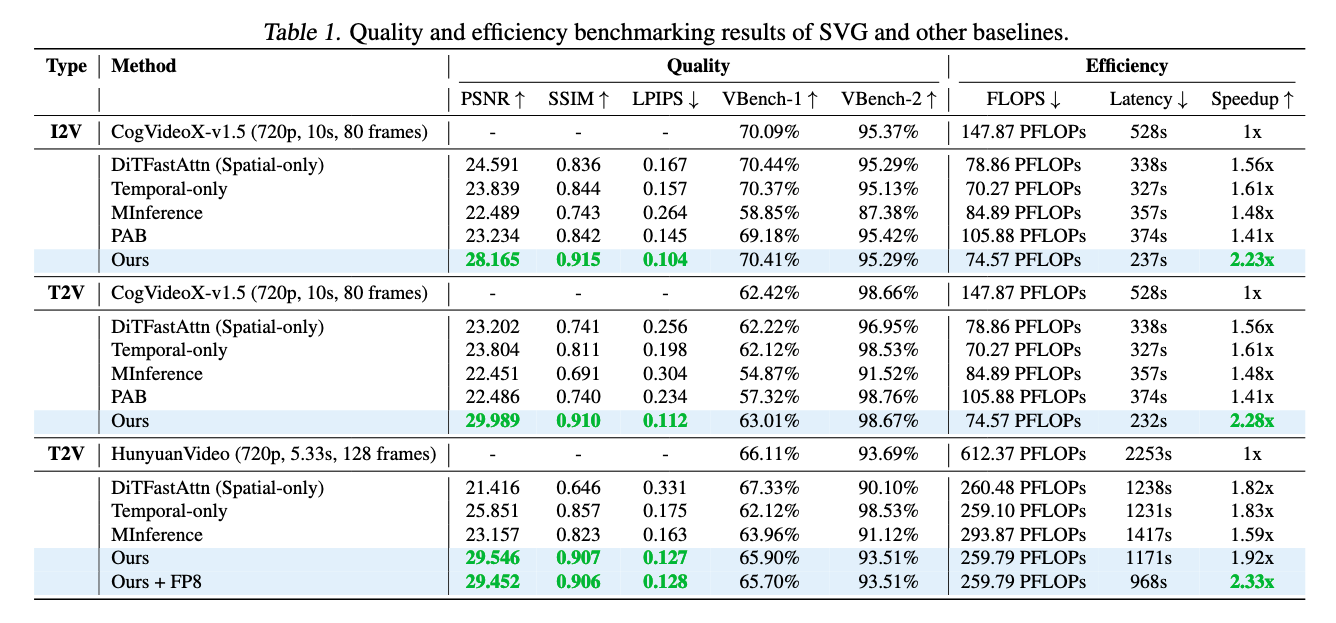
<p>The experiments are conducted on models including CogVideoX-v1.5-I2V, CogVideoX-v1.5-T2V, and HunyuanVideo-T2V to generate 720p resolution videos. The baselines contain sparse attention methods like DiTFastAttn and MInference. Besides, the authors also compare the performance of SVG with the cache-based DiT acceleration method like PAB as baseline. They skip the first 25% of denoising steps for all baseline as they are critical to geneartion quality (<strong>But did authors skip the frist 25% of their works or not? It’s quite confusing here</strong>).</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/SVG_layout_speedup.png" alt="SVG layout speedup" style="width: 48%; display: inline-block;" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/SVG_speedup.png" alt="SVG full speedup" style="width: 48%; display: inline-block;" />
</div>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/SVG_exp_results.png" alt="SVG experiment results" />
</div>

<h2 id="fast-video-generation-with-sliding-tile-attention">Fast Video Generation with SLIDING TILE ATTENTION</h2>

<h3 id="problem-3">Problem</h3>
<p>Same as the previous work, the video generation process is computationally expensive, and due to the quadratic computational complexity with respect to context length, in video it’s resolution and number of frames, the computational cost is even more expensive. Authors want to use the inherently redundancy of video data - adjacent frames are highly correlated and spatially close pixels ten to have stronger relations - to hypothesize <strong>treating every token independently in 3D attention may be unnecessarily expensive, and we can leverage the redundancy to reduce the computational cost</strong>.</p>

<h3 id="observation--proposed-method-1">Observation &amp; Proposed Method</h3>
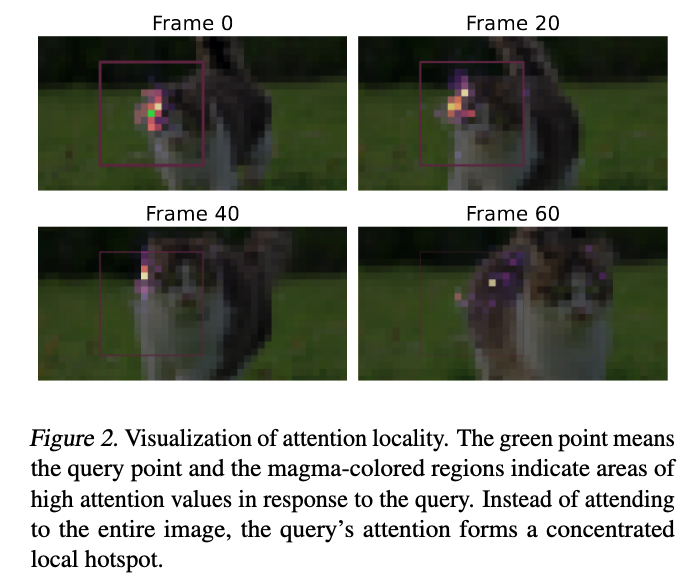
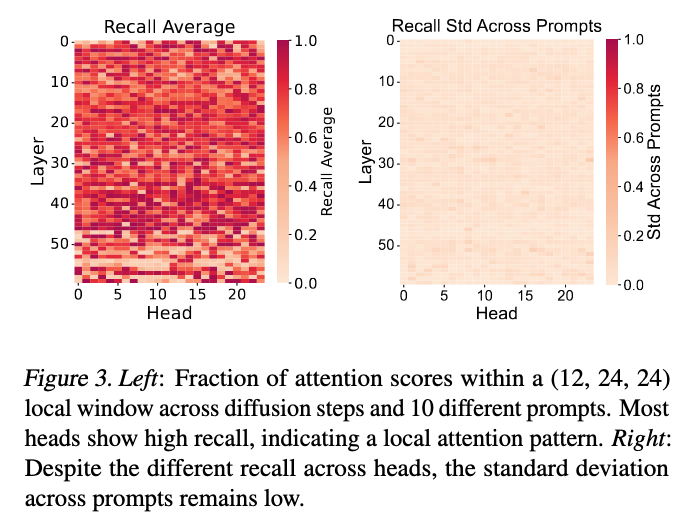
<p>The author first observe that the query’s attention forms a concentrated local spot, mainly the near pixel in the same frame and the near position across frames. Further, they investigate the loal window’s attention scores and found that most heads show high recall (fraction of attention scores concentrated within a local window) and low std across different input prompts.</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/STA_attn_locality.png" alt="STA attn locality" style="width: 48%; display: inline-block;" />
<img src="https://dianyo.github.io//images/ICML2025_videogen/STA_attn_window_investigation.png" alt="STA attn window investigation" style="width: 48%; display: inline-block;" />
</div>

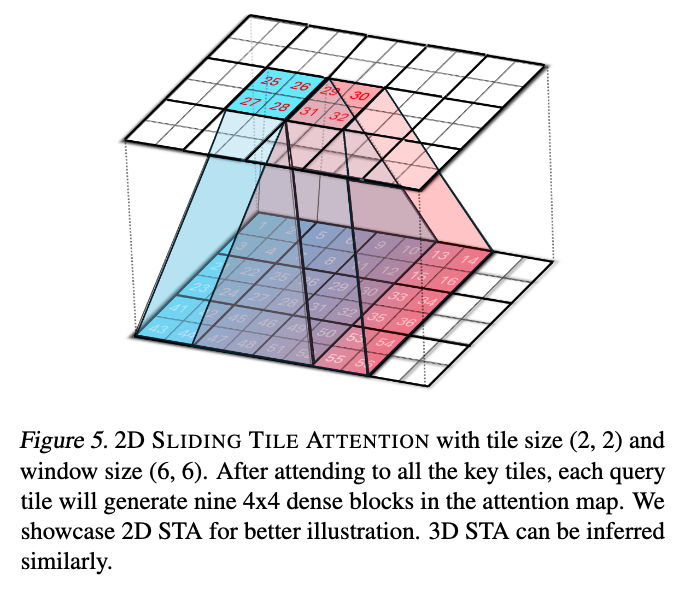
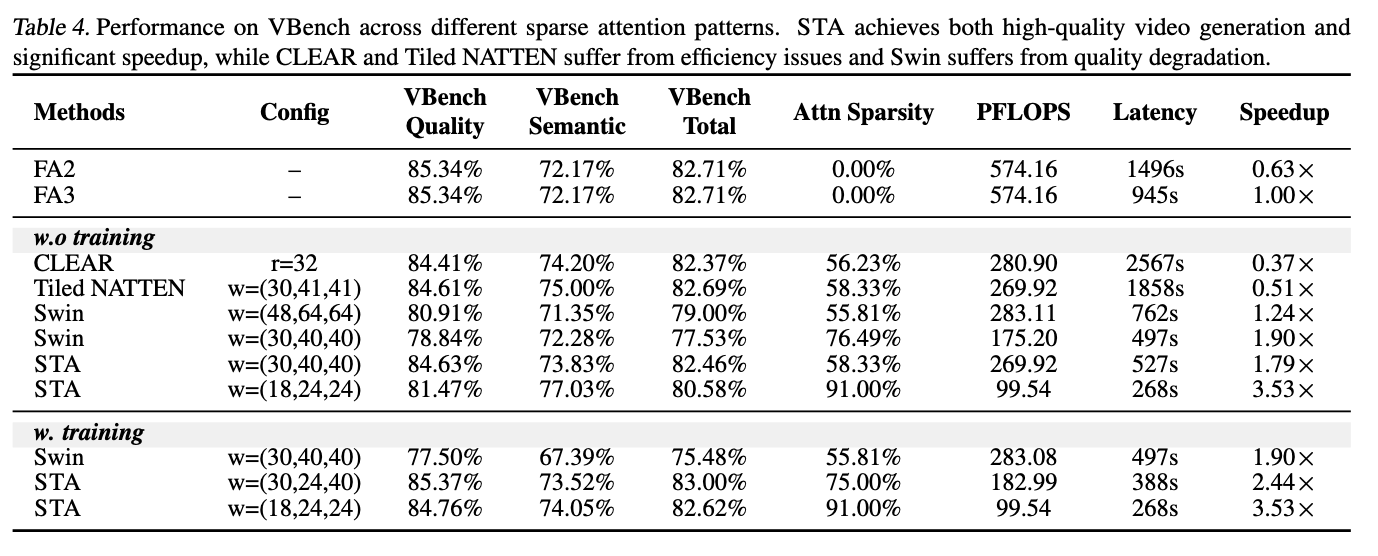
<p>Building on the observation, sliding window attention (SWA) is an ideal candidate to reduce the computational cost. However, existing 2D or 3D SWA implementations are inefficiency due to high overhead from creating a highly irregular attention mask for each window which comes from each query attends to a distinct set of keys, resulting in a zigzag pattern in the attention map and form a lot of mixed blocks. The authors further revisit this sliding windown mechanism and propose a new method called Sliding Tile Attention (STA) to reduce the overhead. STA organizes queries and keys into tiles, all queried in the same tile attent ot the same set of keys whithin their common local window. By setting the tile areq equal to the block size implement by FlashAttention, we can eliminate the mixed blocks and improving computational efficiency.</p>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/STA_sta.png" alt="STA algorithm" />
</div>

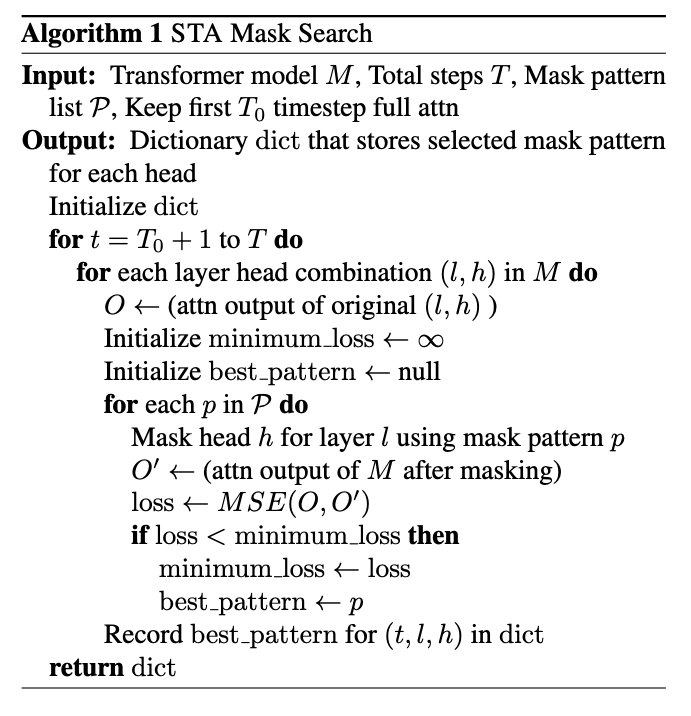
<p>Next, the authors propose an algorithm to search for the optimal window size for each head by averaging the mask-search loss across just 16 prompts using predefined pattern list. They kept full attention for the first ( T_0 ) steps and then switch to STA for the rest of the denoising process. Besides, the authors also propose a learning method by fixing the window size and fine-tuning the model by attention distillation loss between STA and original full attention + finaly lyaer alignment loss + the data loss following the flow matching loss.</p>

<div style="display: flex; justify-content: center; gap: 1rem; align-items: flex-start; flex-wrap: wrap;">

  <!-- Left: main image -->
  <div style="flex: 1 1 45%;">
    <img src="https://dianyo.github.io//images/ICML2025_videogen/STA_search_algo.png" alt="STA search algorithm" style="width: 100%; max-width: 100%;" />
  </div>

  <!-- Right: vertical stack -->
  <div style="flex: 1 1 45%; display: flex; flex-direction: column; gap: 0.5rem;">
    <img src="https://dianyo.github.io//images/ICML2025_videogen/STA_finetune1.png" alt="STA finetune 1" style="width: 100%;" />
    <img src="https://dianyo.github.io//images/ICML2025_videogen/STA_finetune2.png" alt="STA finetune 2" style="width: 100%;" />
    <img src="https://dianyo.github.io//images/ICML2025_videogen/STA_finetune3.png" alt="STA finetune 3" style="width: 100%;" />
    <img src="https://dianyo.github.io//images/ICML2025_videogen/STA_finetune4.png" alt="STA finetune 4" style="width: 100%;" />
  </div>

</div>

<h3 id="experiments--results-3">Experiments &amp; Results</h3>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/STA_main_exp.png" alt="STA main experiment results" />
</div>

<div style="text-align: center; width: 100%; margin: 0 auto;">
<img src="https://dianyo.github.io//images/ICML2025_videogen/STA_exp_kernel.png" alt="STA kernel" />
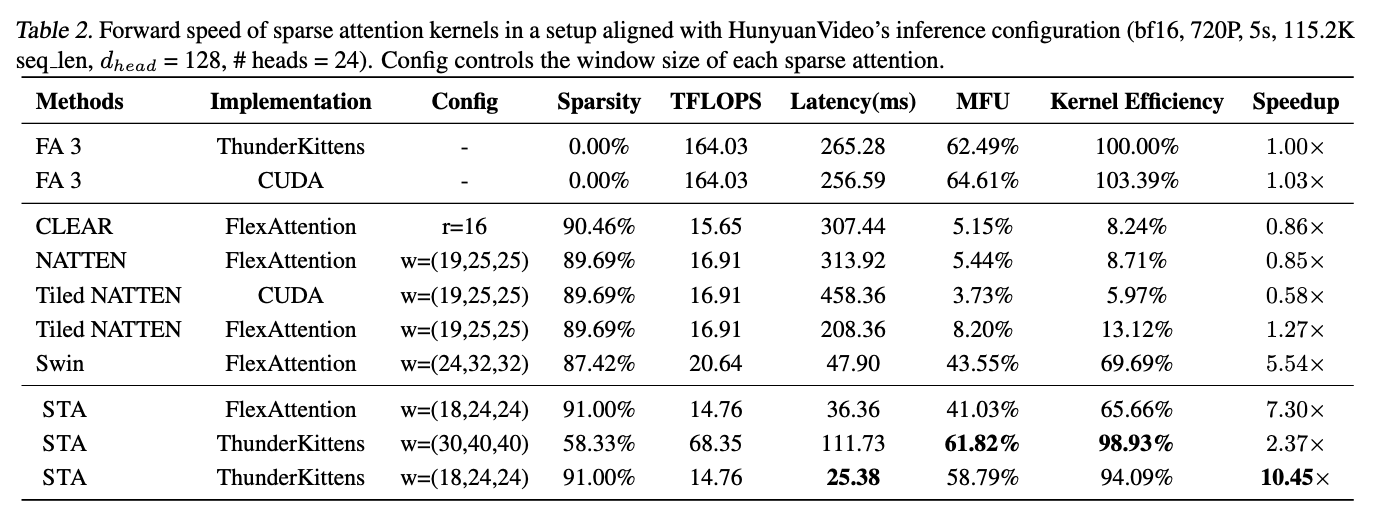
</div>]]></content><author><name></name></author><summary type="html"><![CDATA[In this post, I’ll quickly summarize the video generation related research that I found interesting in ICML2025.]]></summary></entry></feed>